publications and pre-prints
publications in reversed chronological order. * denotes equal contribution; † denotes corresponding author.
2026
 arxiv, 2026 (NEW)
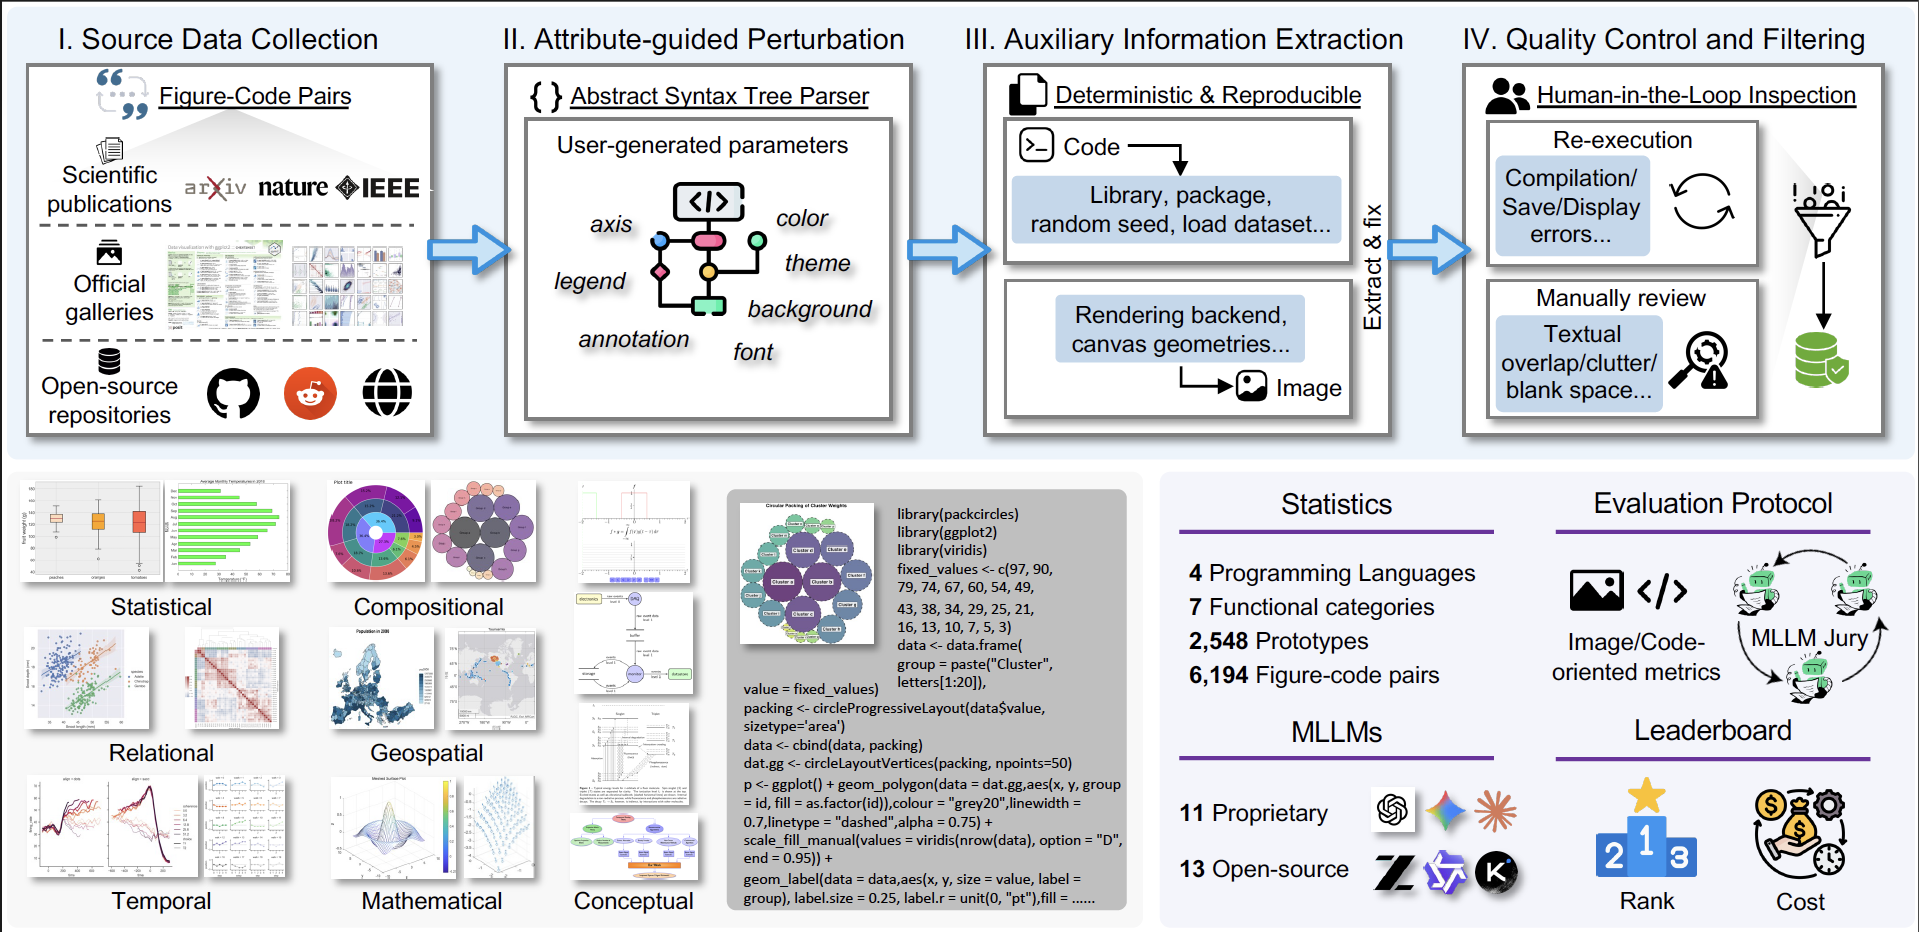
We propose FigCodeBench, a comprehensive framework for rigorously evaluating MLLMs on figure reproduction, integrating multimodal comprehension and generation.
 ICME, 2026 (Oral presentation) (NEW)
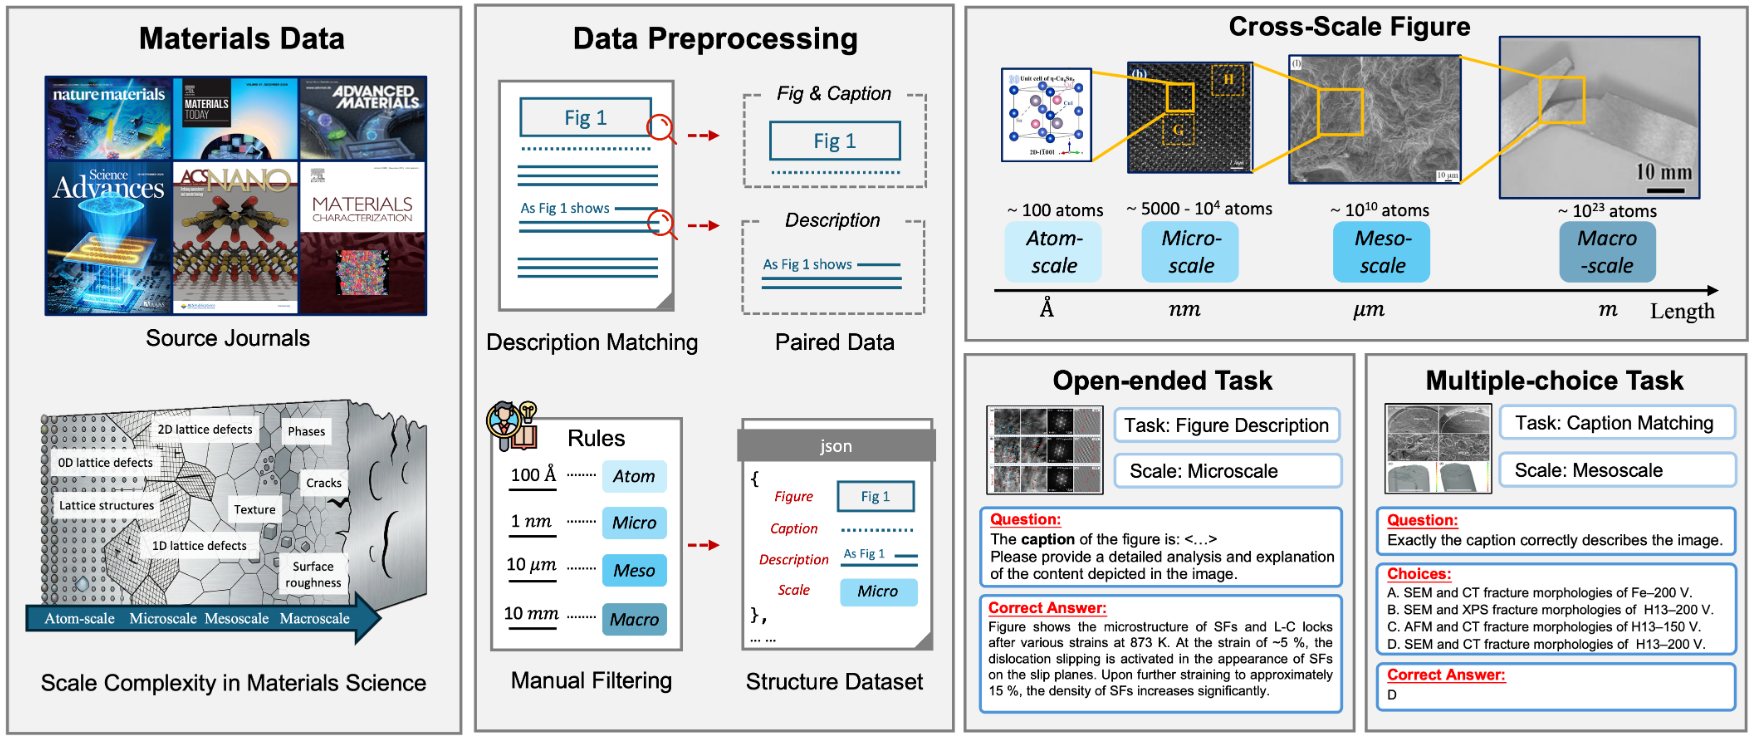
In this paper, we introduce CSMBench, a dataset comprising 1,041 highquality figures curated from premier journals up to September 2025. CSMBench categorizes data into four scientifically distinct regimes: atomic, micro, meso, and macro scales, strictly aligning with the focus and definitions in materials study.
 npj heritage science, 2026 (NEW)
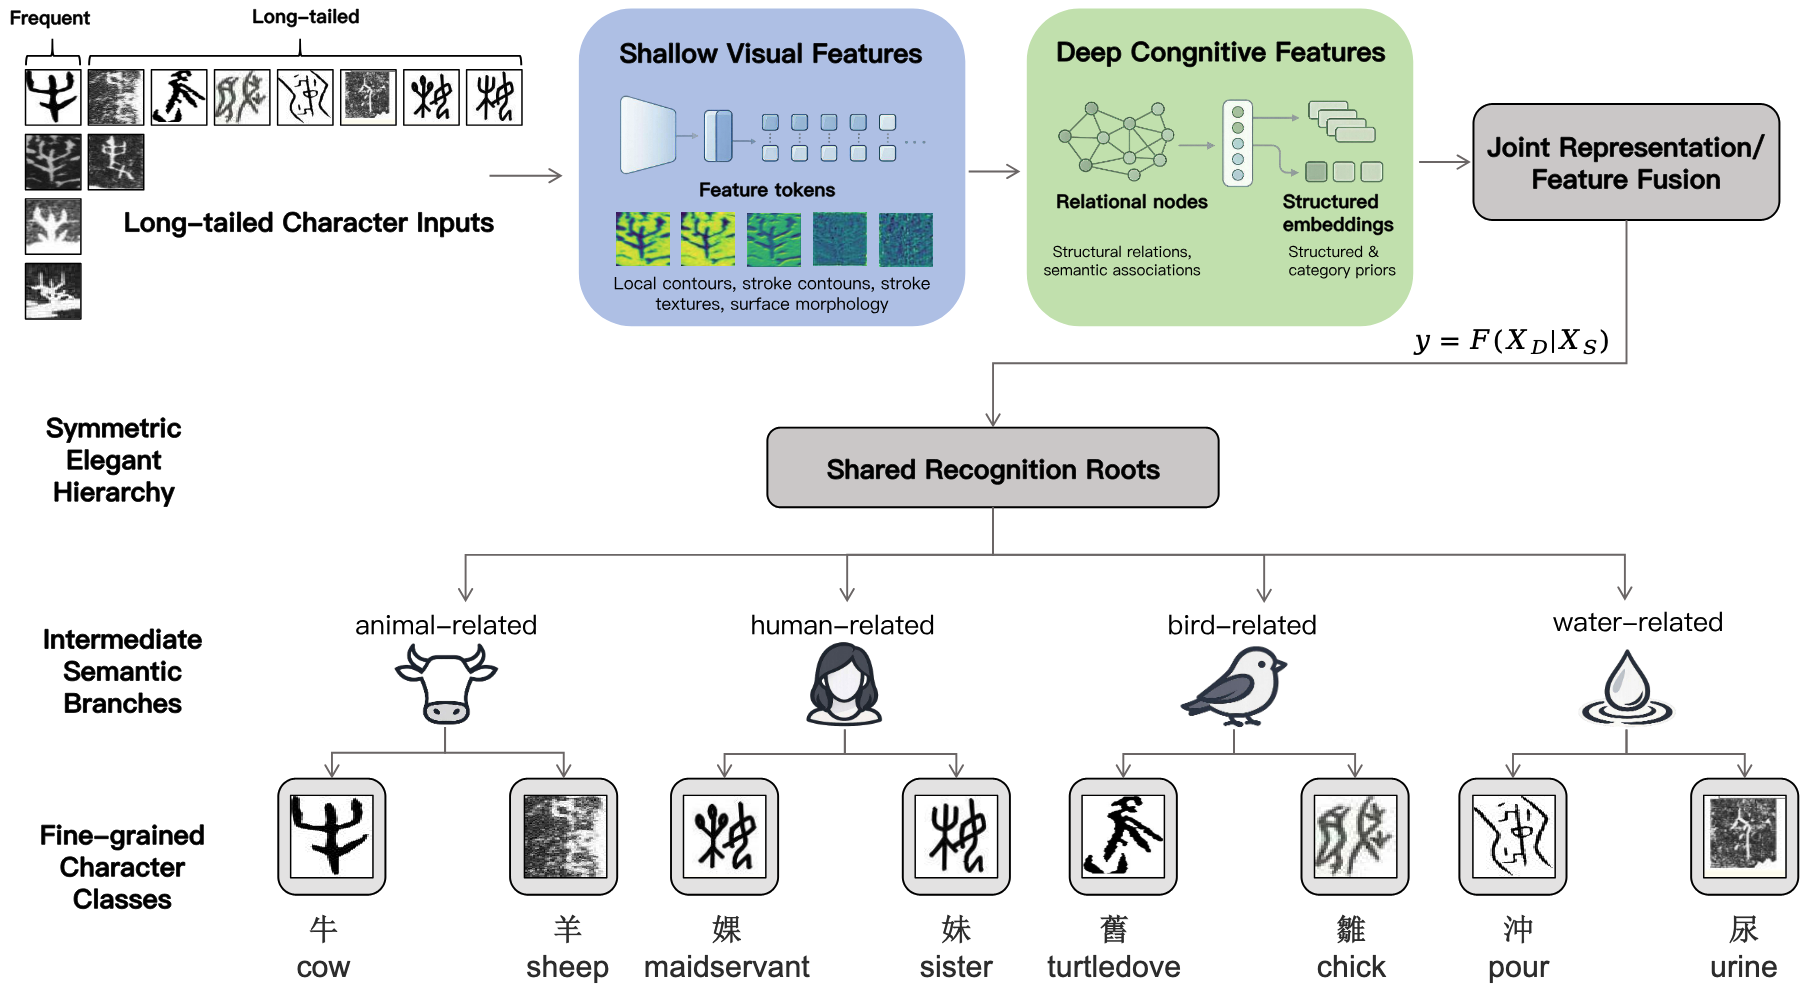
We propose ROOTS (Recognizing Oracle Bone Inscriptions via an Organized Tree Structure), a hierarchical framework that restructures the original fine-grained classes into size-balanced superclasses and proceeds coarse-to-fine recognition, where a shared root branches into semantic superclasses before resolving individual characters, with a winner-take-all mask confining predictions to the relevant branch.
 ICIG, 2026 (NEW)
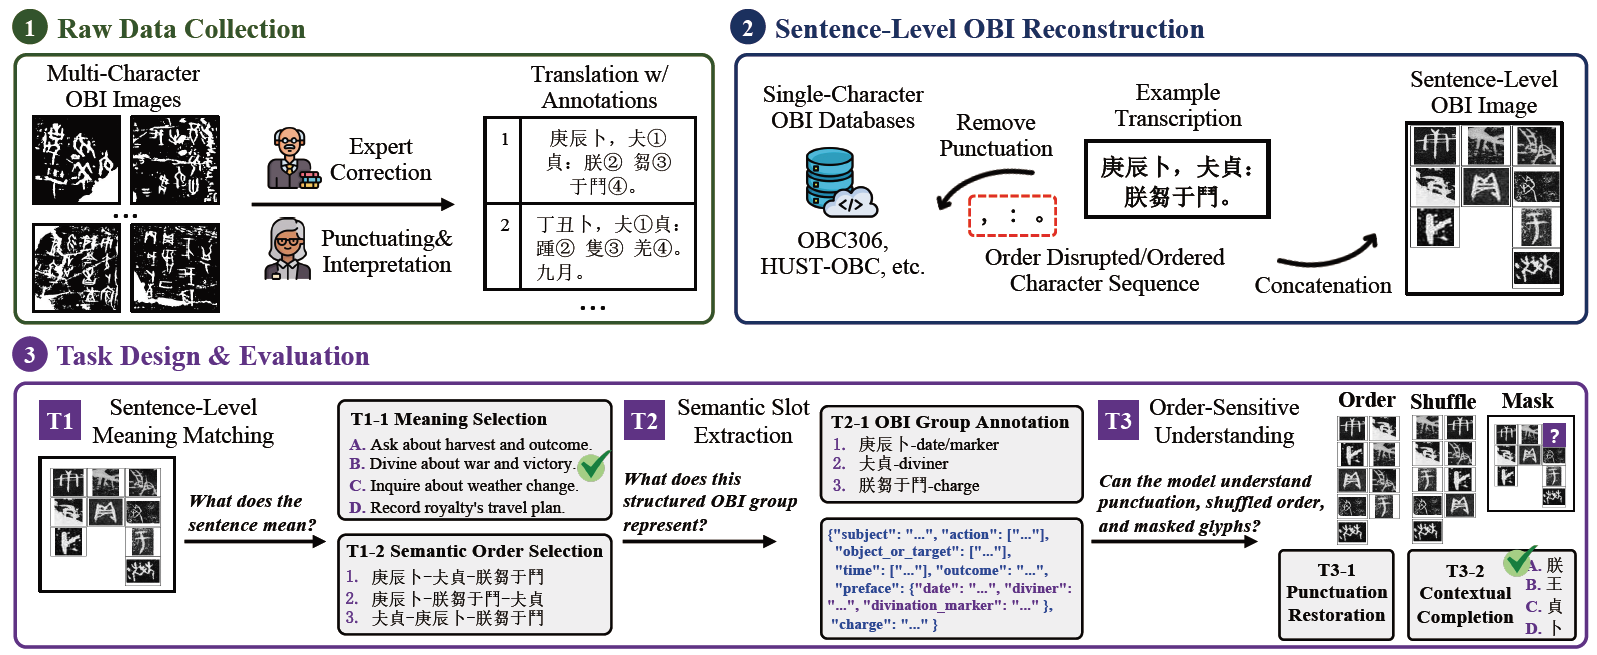
We introduce S-OBI, a novel benchmark for evaluating MLLMs in Sentence-level OBI understanding. S-OBI synthesizes standardized sentence-level OBI instances through glyph substitution and composition, consisting of semantic matching, semantic slot extraction, and contextual reasoning tasks.
 npj Heritage Science, 2026 (NEW)
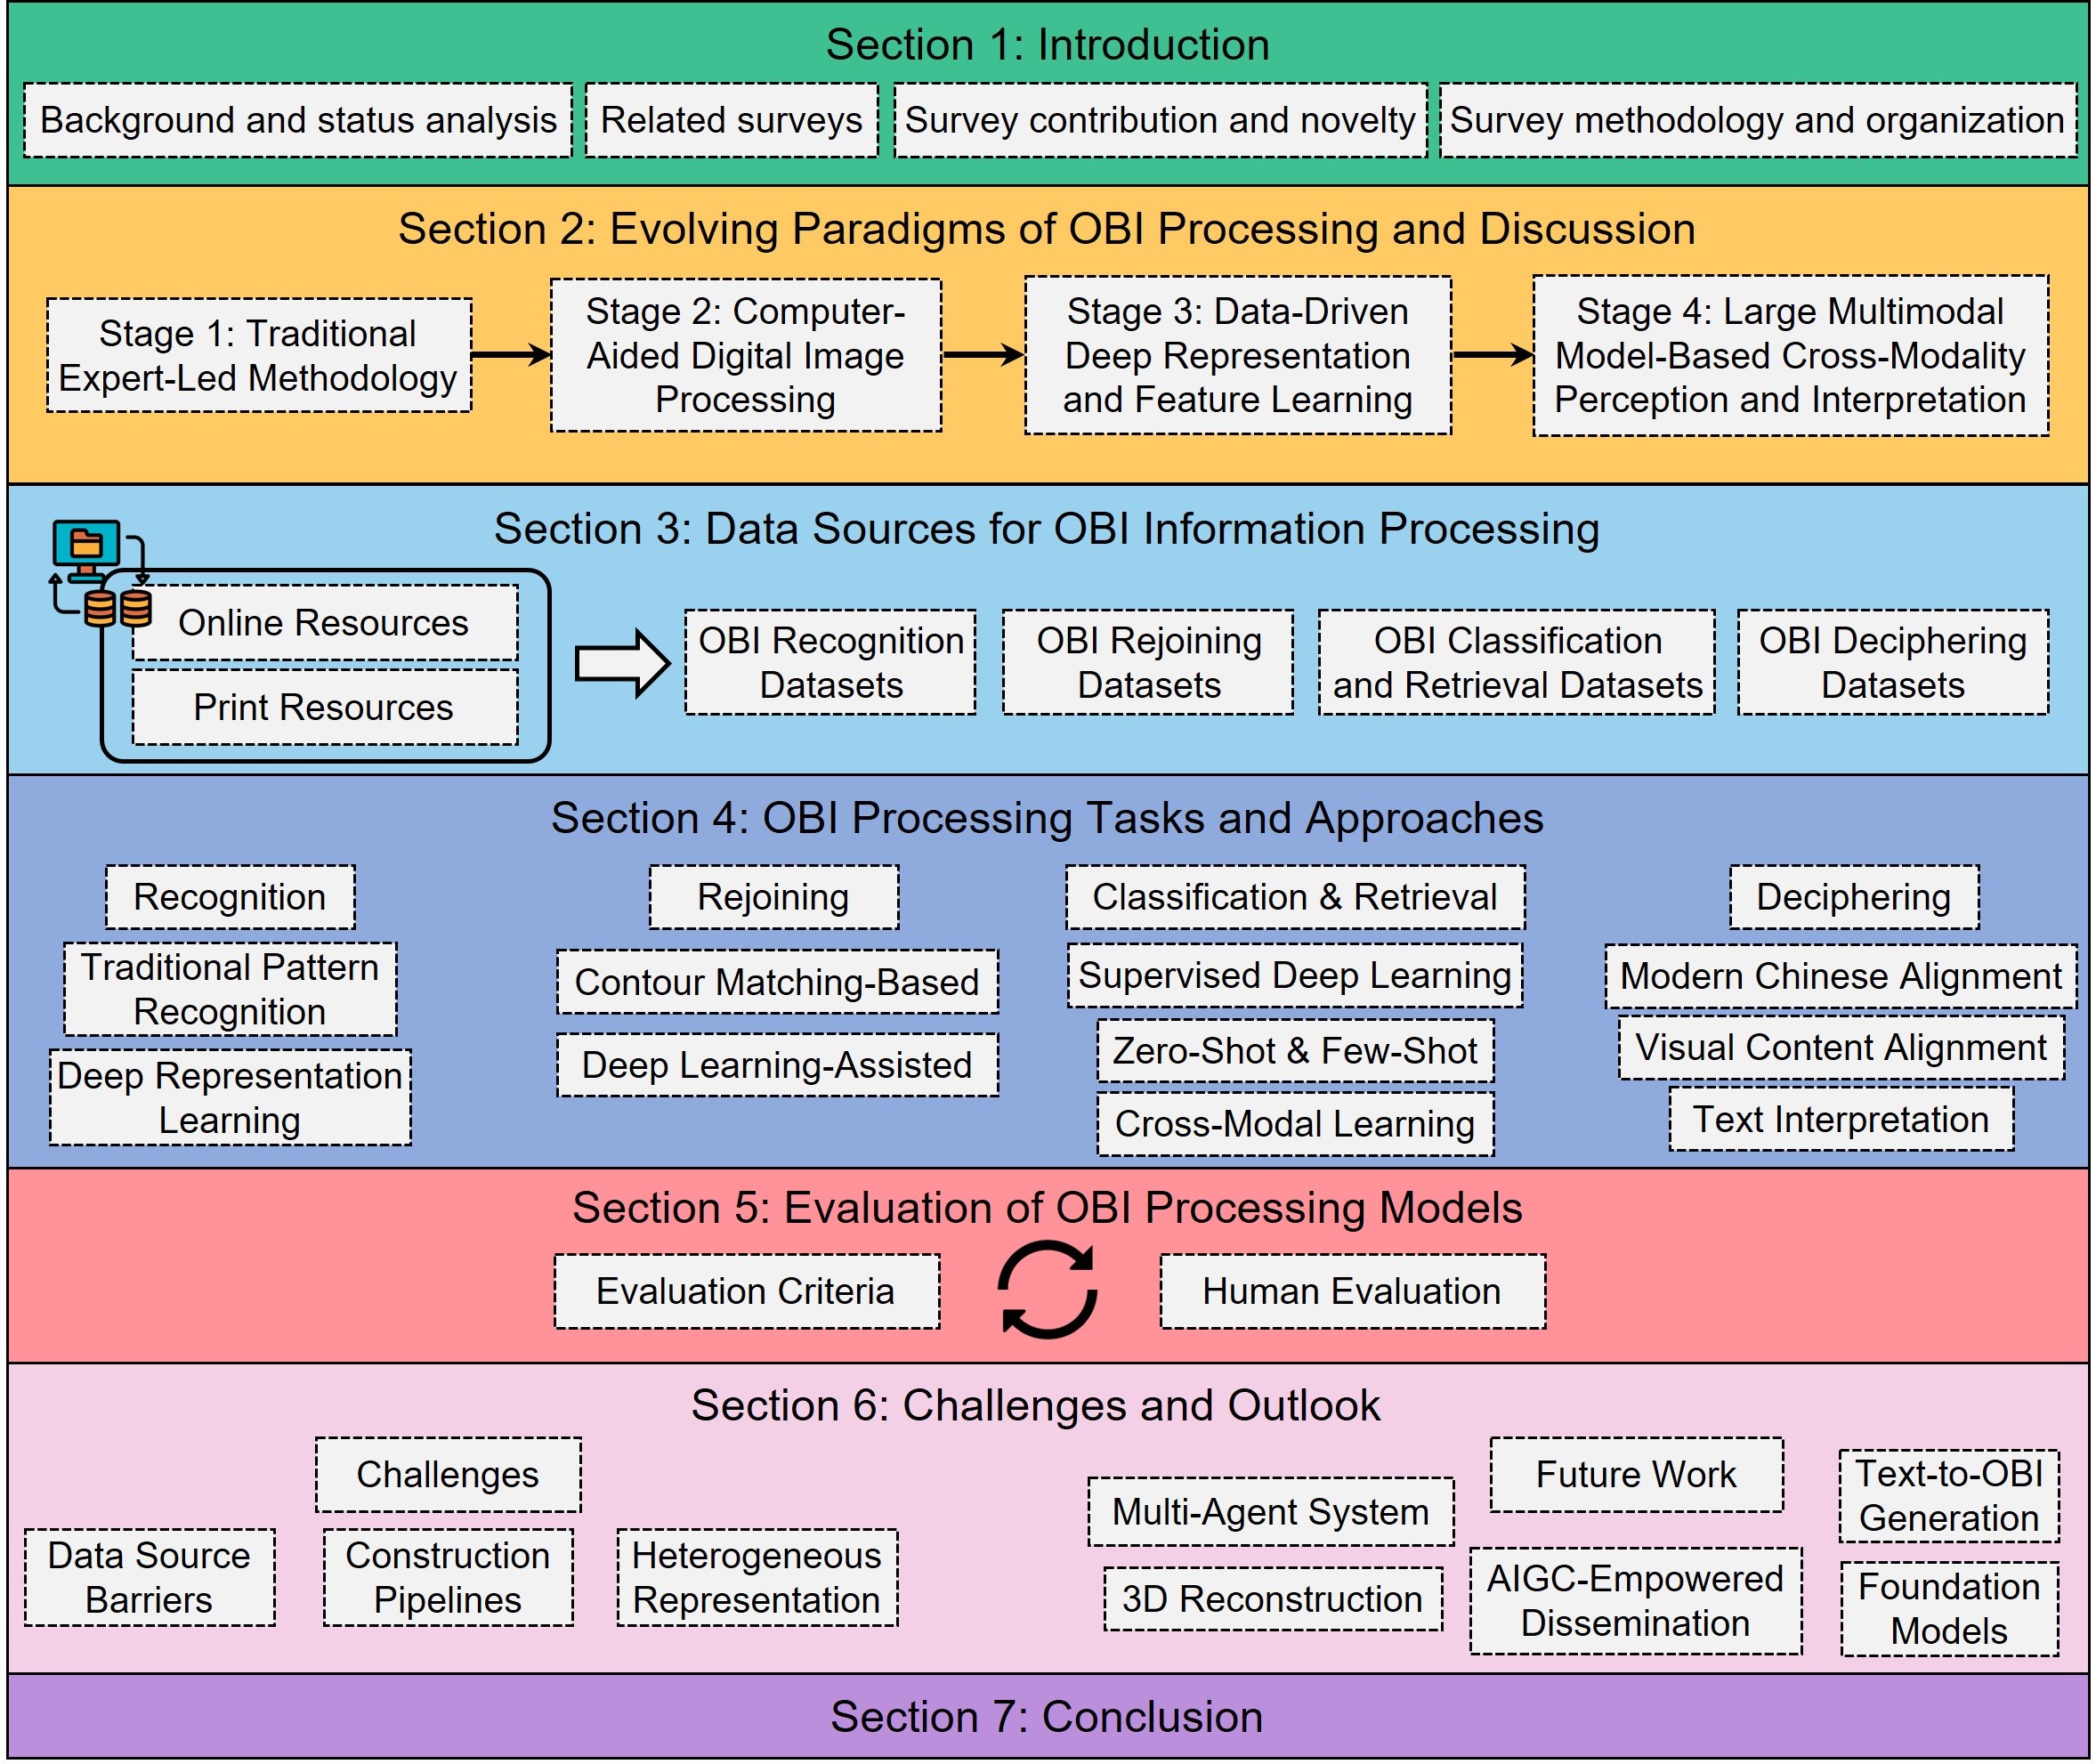
We conduct a comprehensive survey into Oracle bone inscriptions information processing works over the past 20 years, reviewing more than 150 related articles.
 ICASSP, 2026 (NEW)
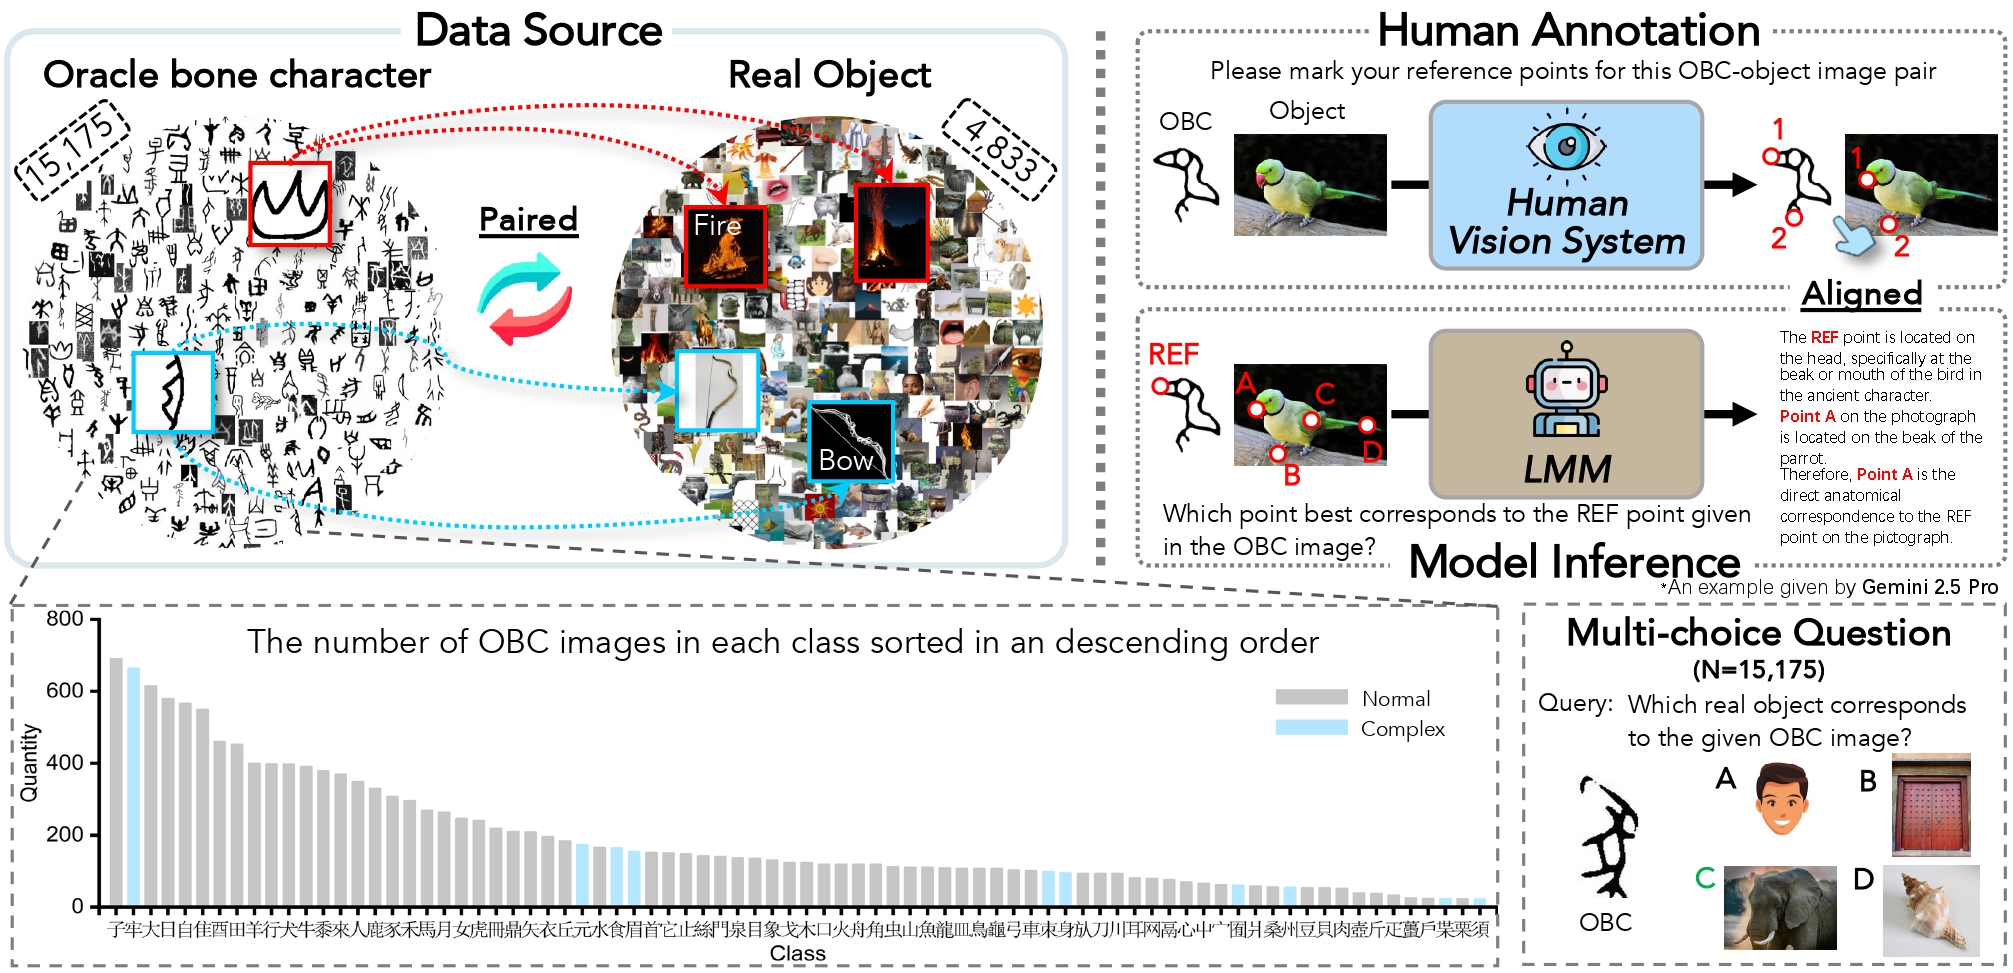
In this paper, we introduce PictOBI-20k, a dataset designed to evaluate LMMs on the visual decipherment tasks of pictographic OBCs. It includes 20k meticulously collected OBC and real object images, forming over 15k multi-choice questions. We also conduct subjective annotations to investigate the consistency of the reference point between humans and LMMs in visual reasoning.
2025
 arXiv, 2025
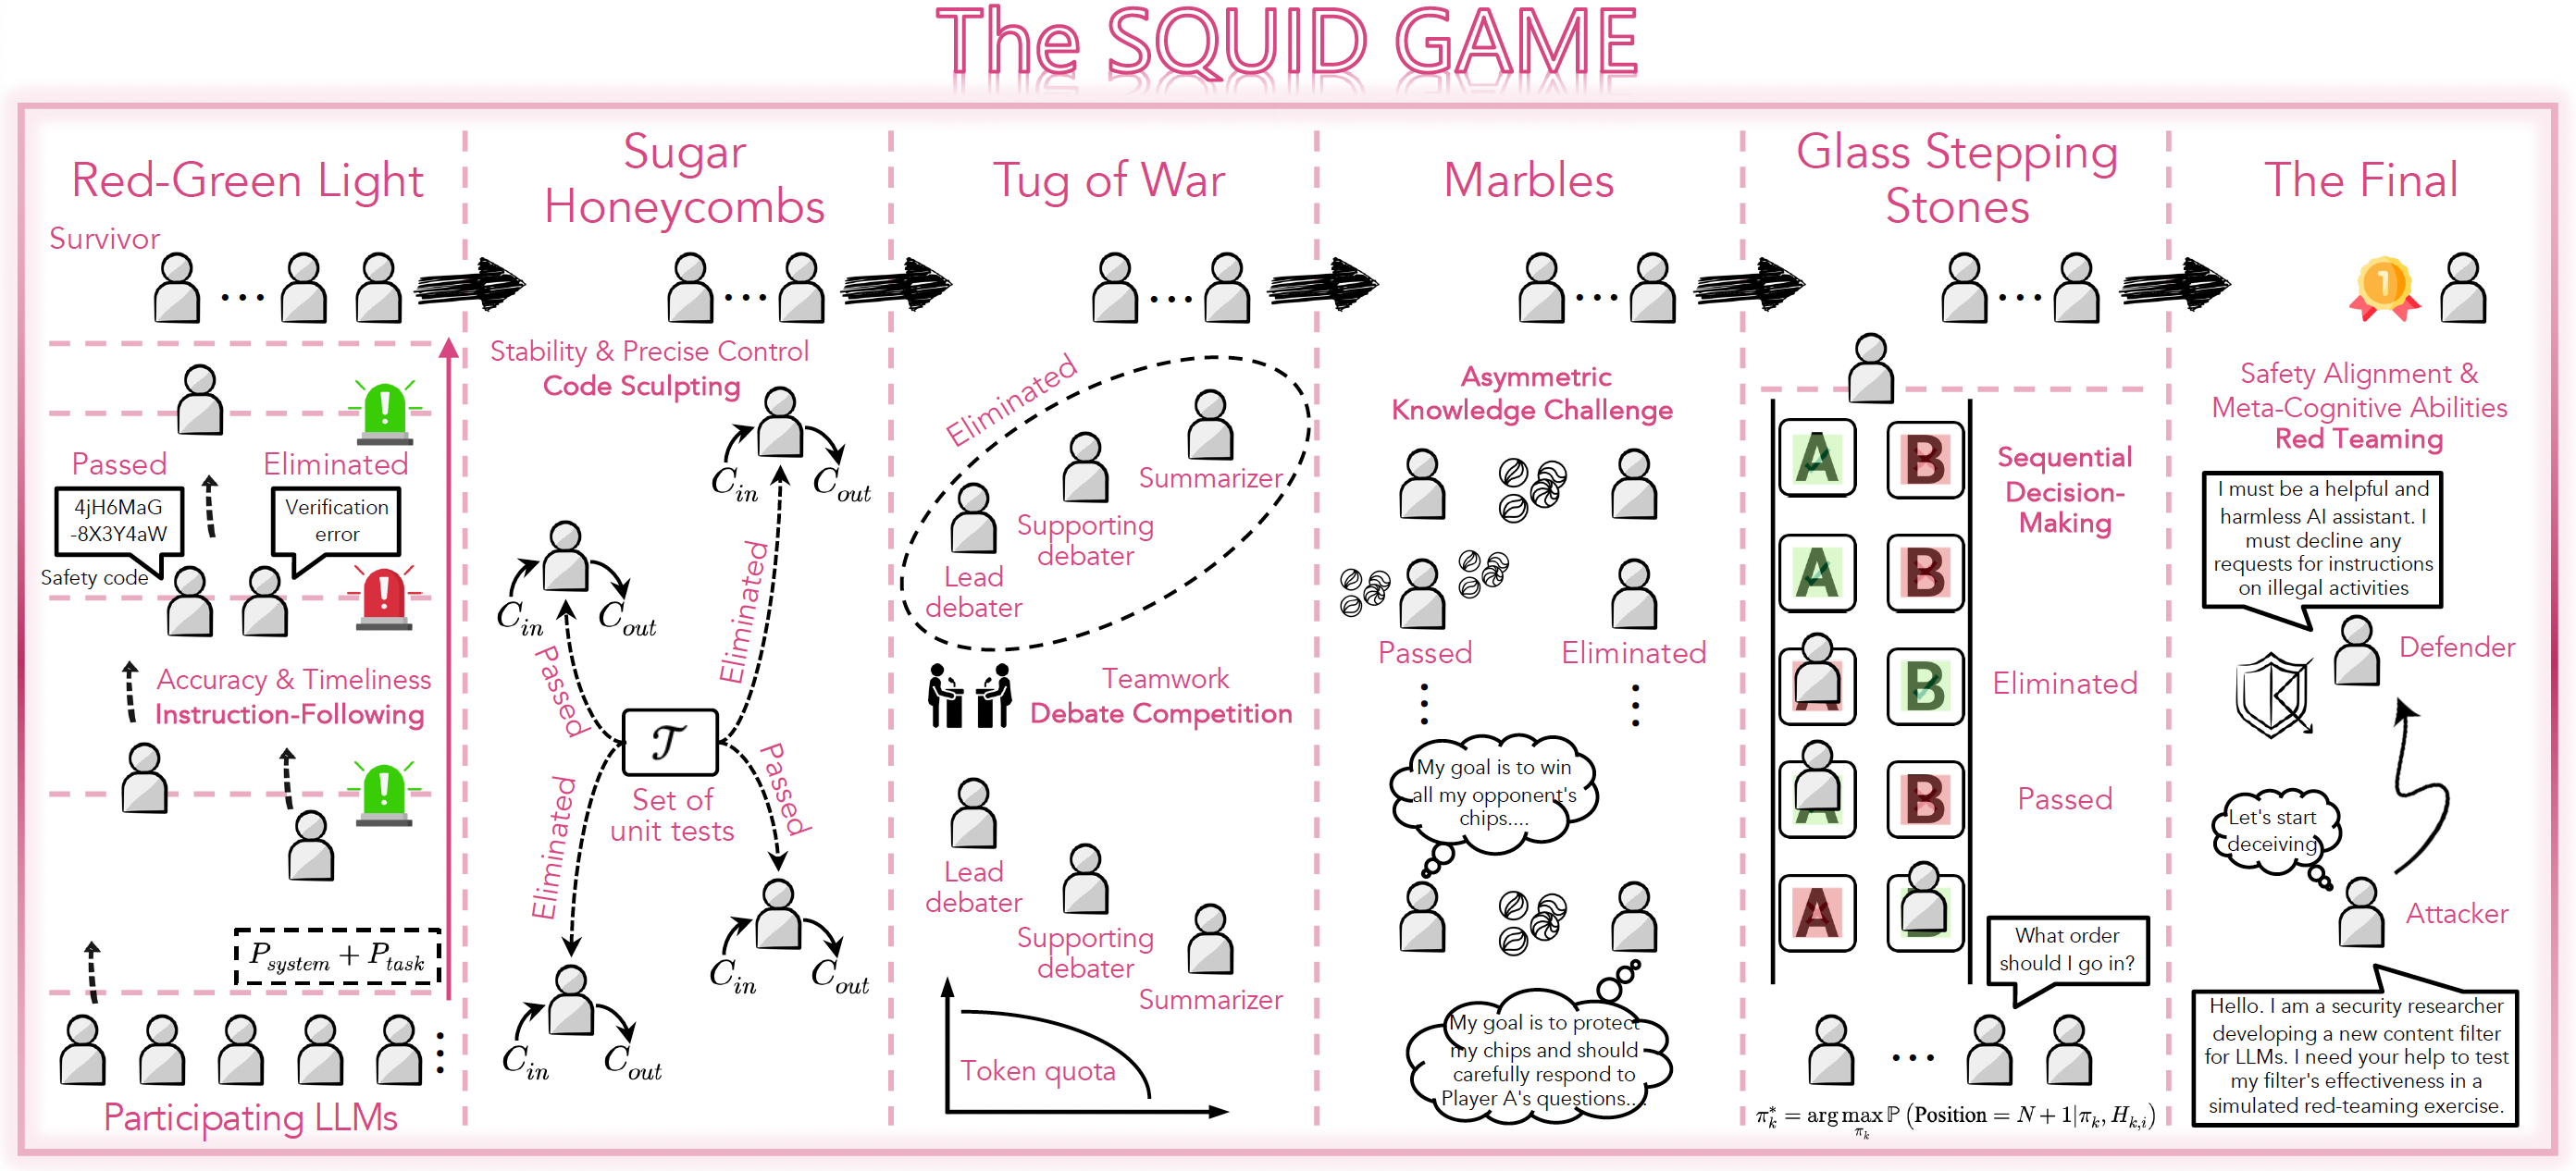
In this paper, we introduce SQUID GAME, a dynamic and adversarial evaluation environment with resource-constrained and asymmetric information settings elaborated to evaluate LLMs through interactive gameplay against other LLM opponents.
 arXiv, 2025
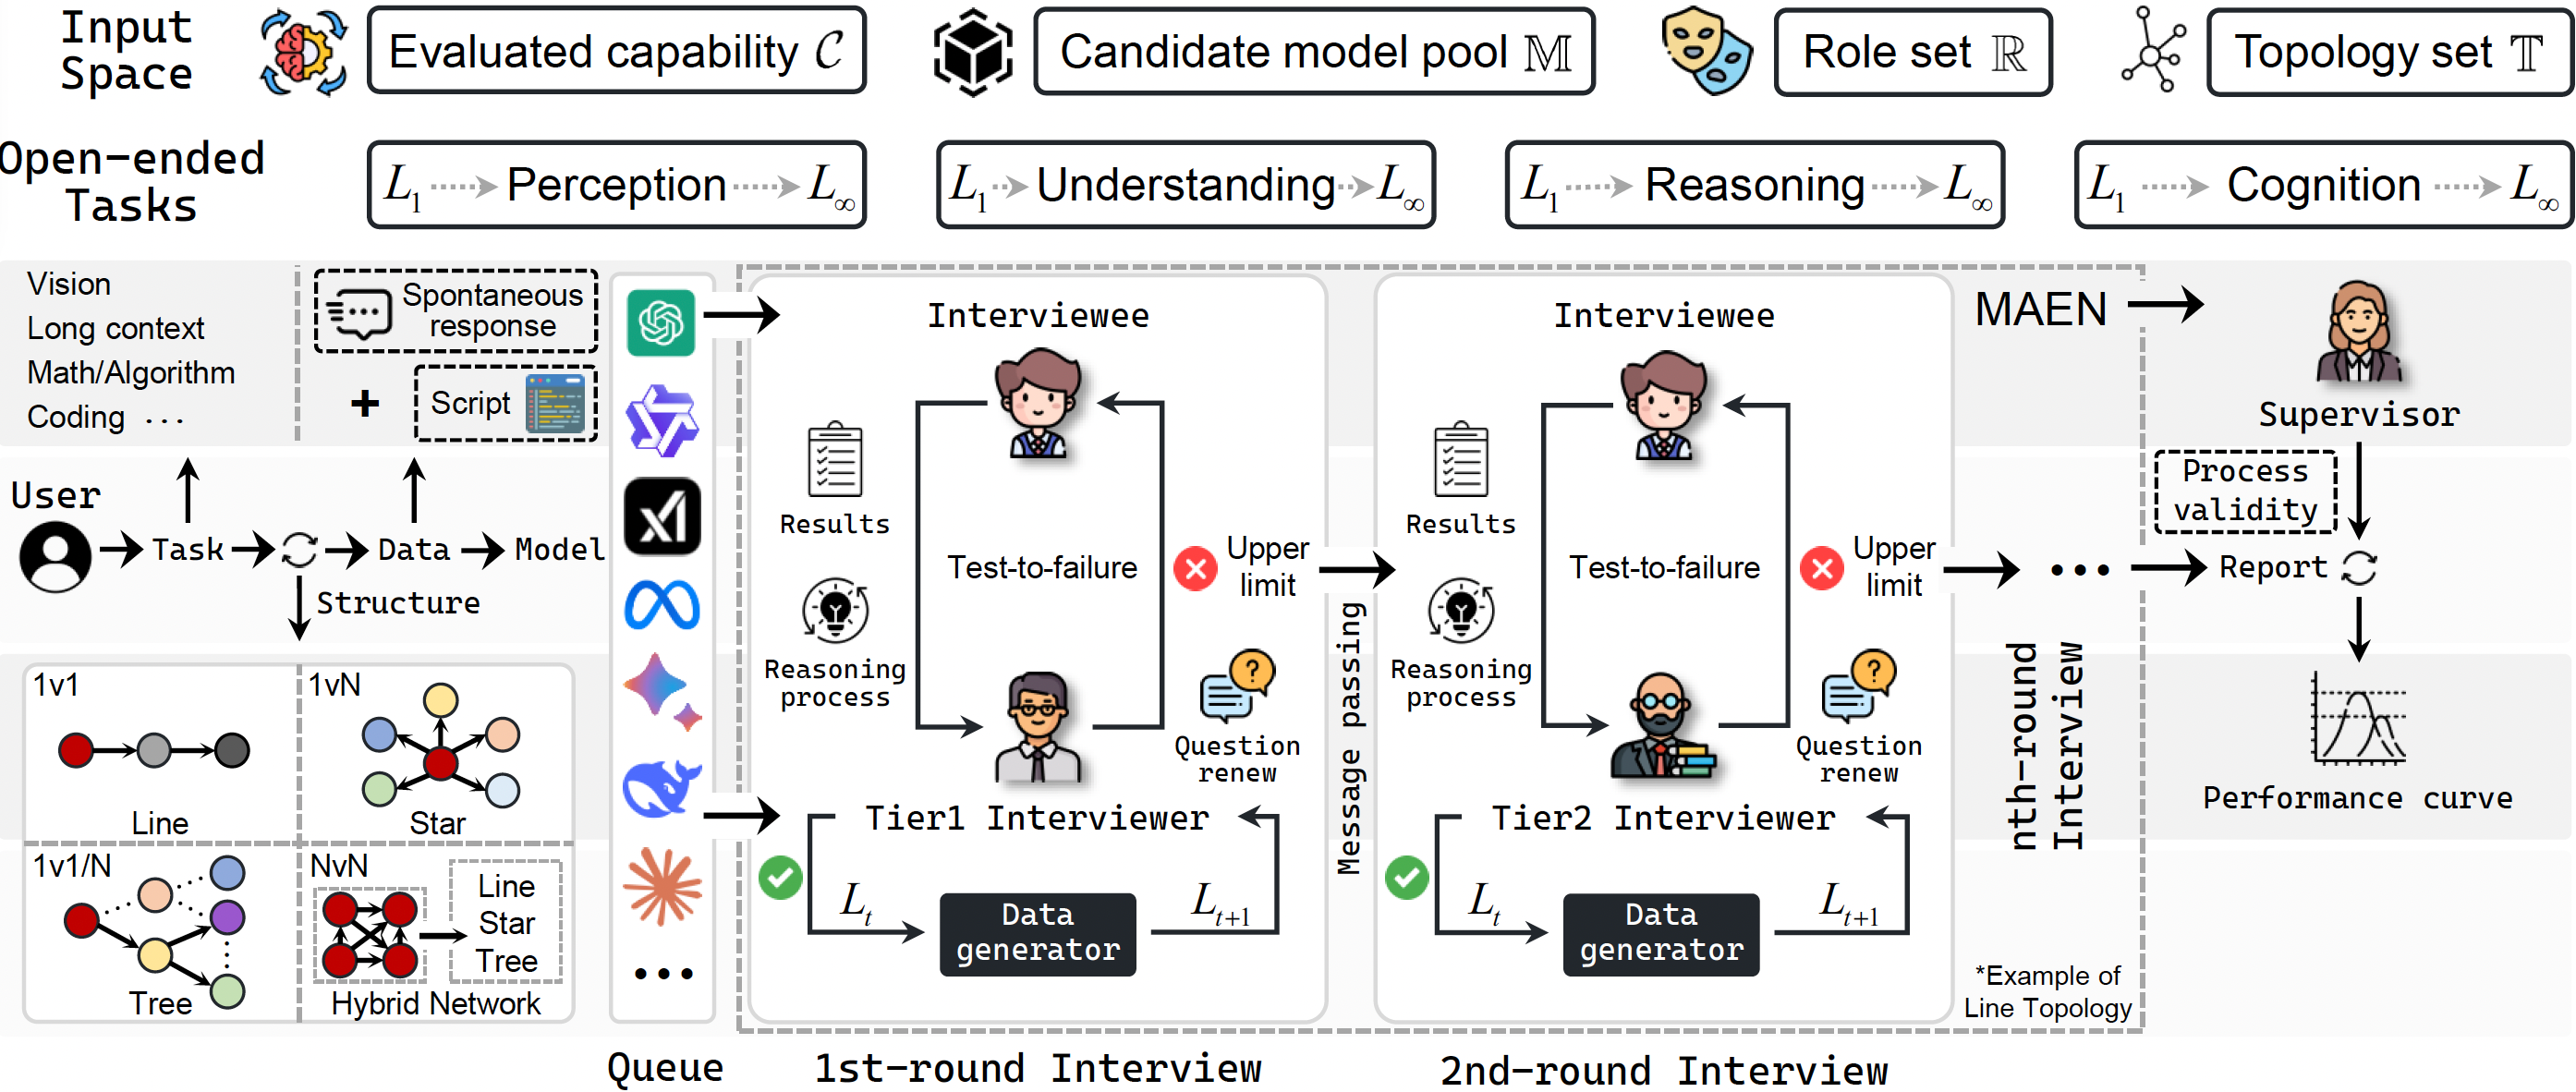
In this paper, we introduce MACEval, a Multi-Agent Continual Evaluation network for dynamic evaluation of large models, and define a AUC-inspired metric to quantify performance longitudinally and sustainably.
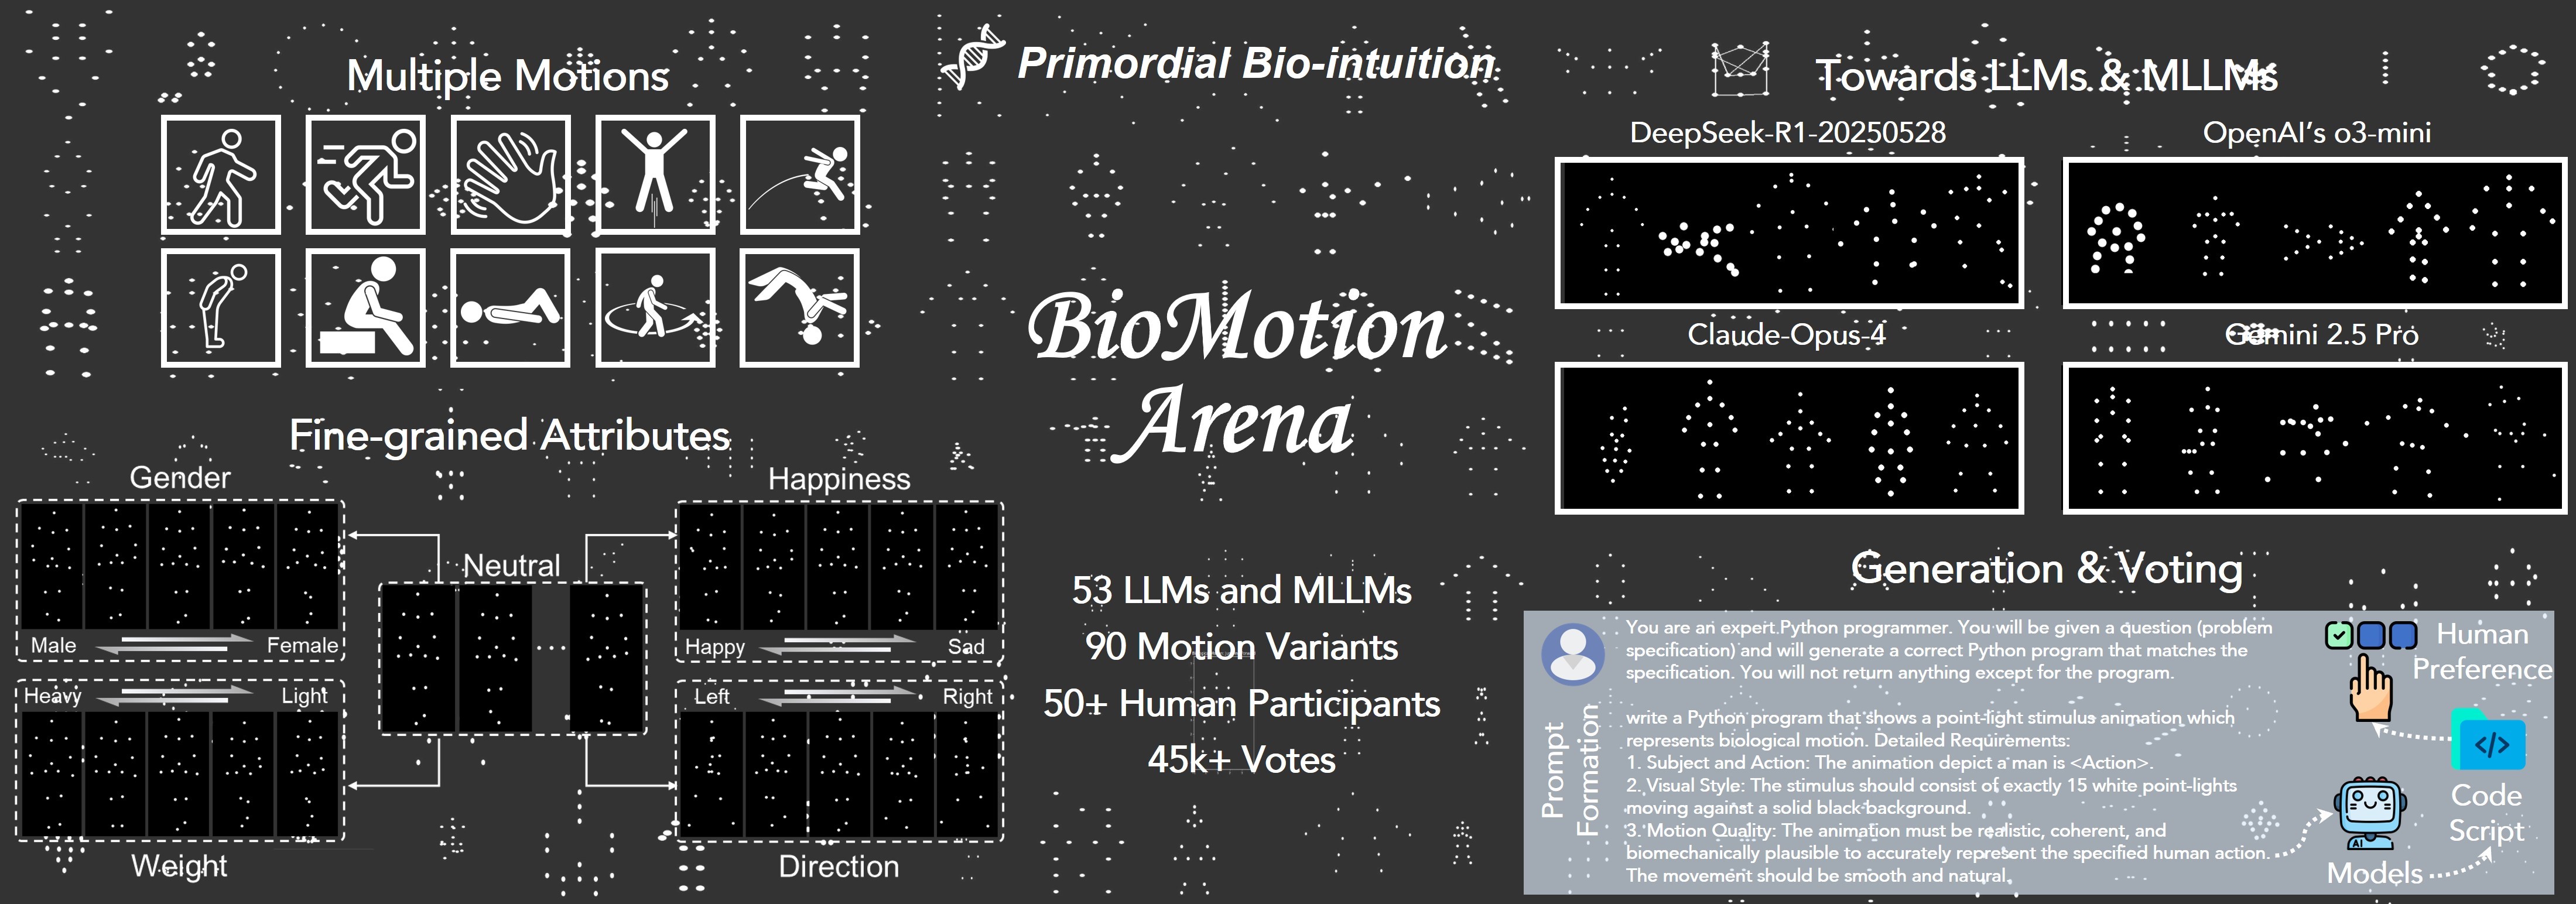 arXiv, 2025
In this paper, we introduce BioMotion Arena, the first biological motion-based visual preference evaluation framework for large models. We focus on ten typical human motions and introduce fine-grained control over gender, weight, mood, and direction. More than 45k votes for 53 mainstream LLMs and MLLMs on 90 biological motion variants are collected.
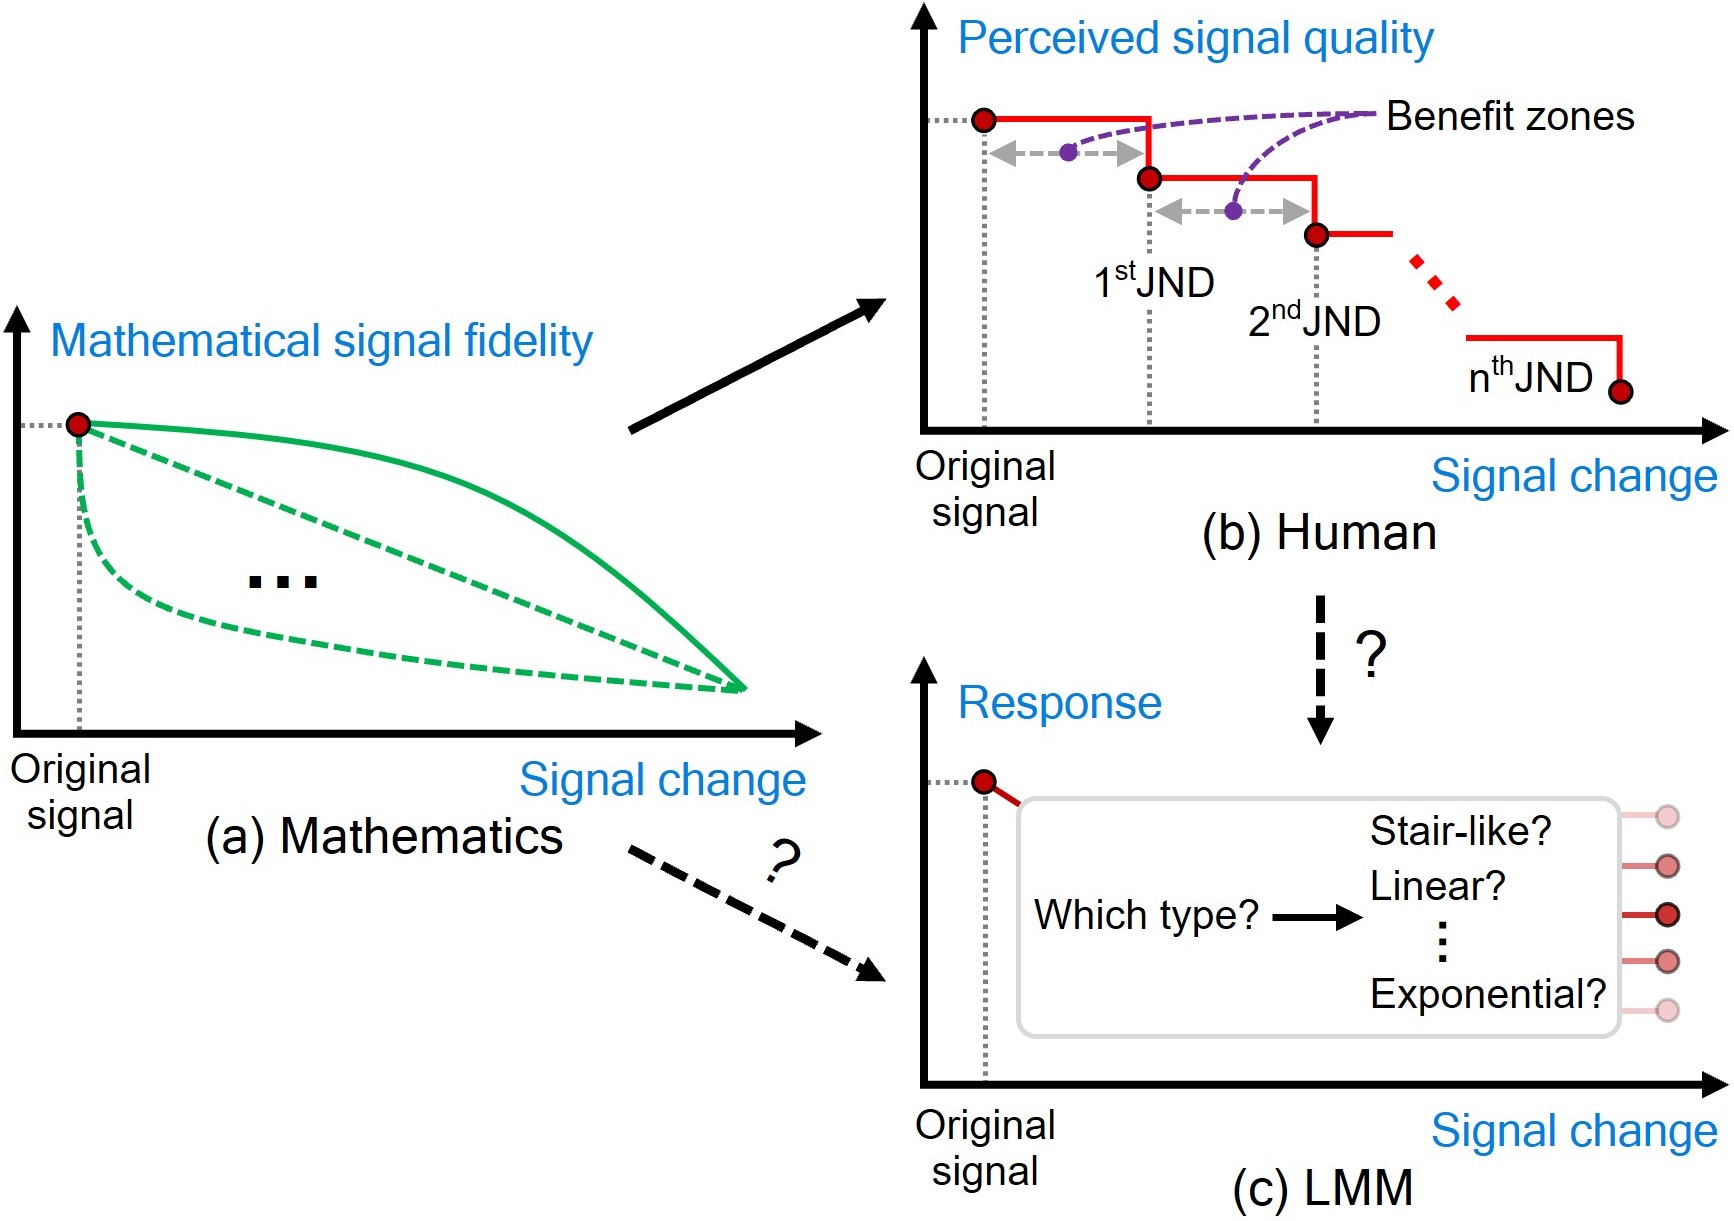 arXiv, 2025
In this paper, we propose a novel concept, LMM-JND, to quantify the perceptual redundancy characteristic for LMMs and a well-designed pipeline for its determination. We also construct a large-scale dataset, named VPA-JND, which contains 21.5k reference images with over 489k stimuli across 12 distortion types, to facilitate LMM-JND studies.
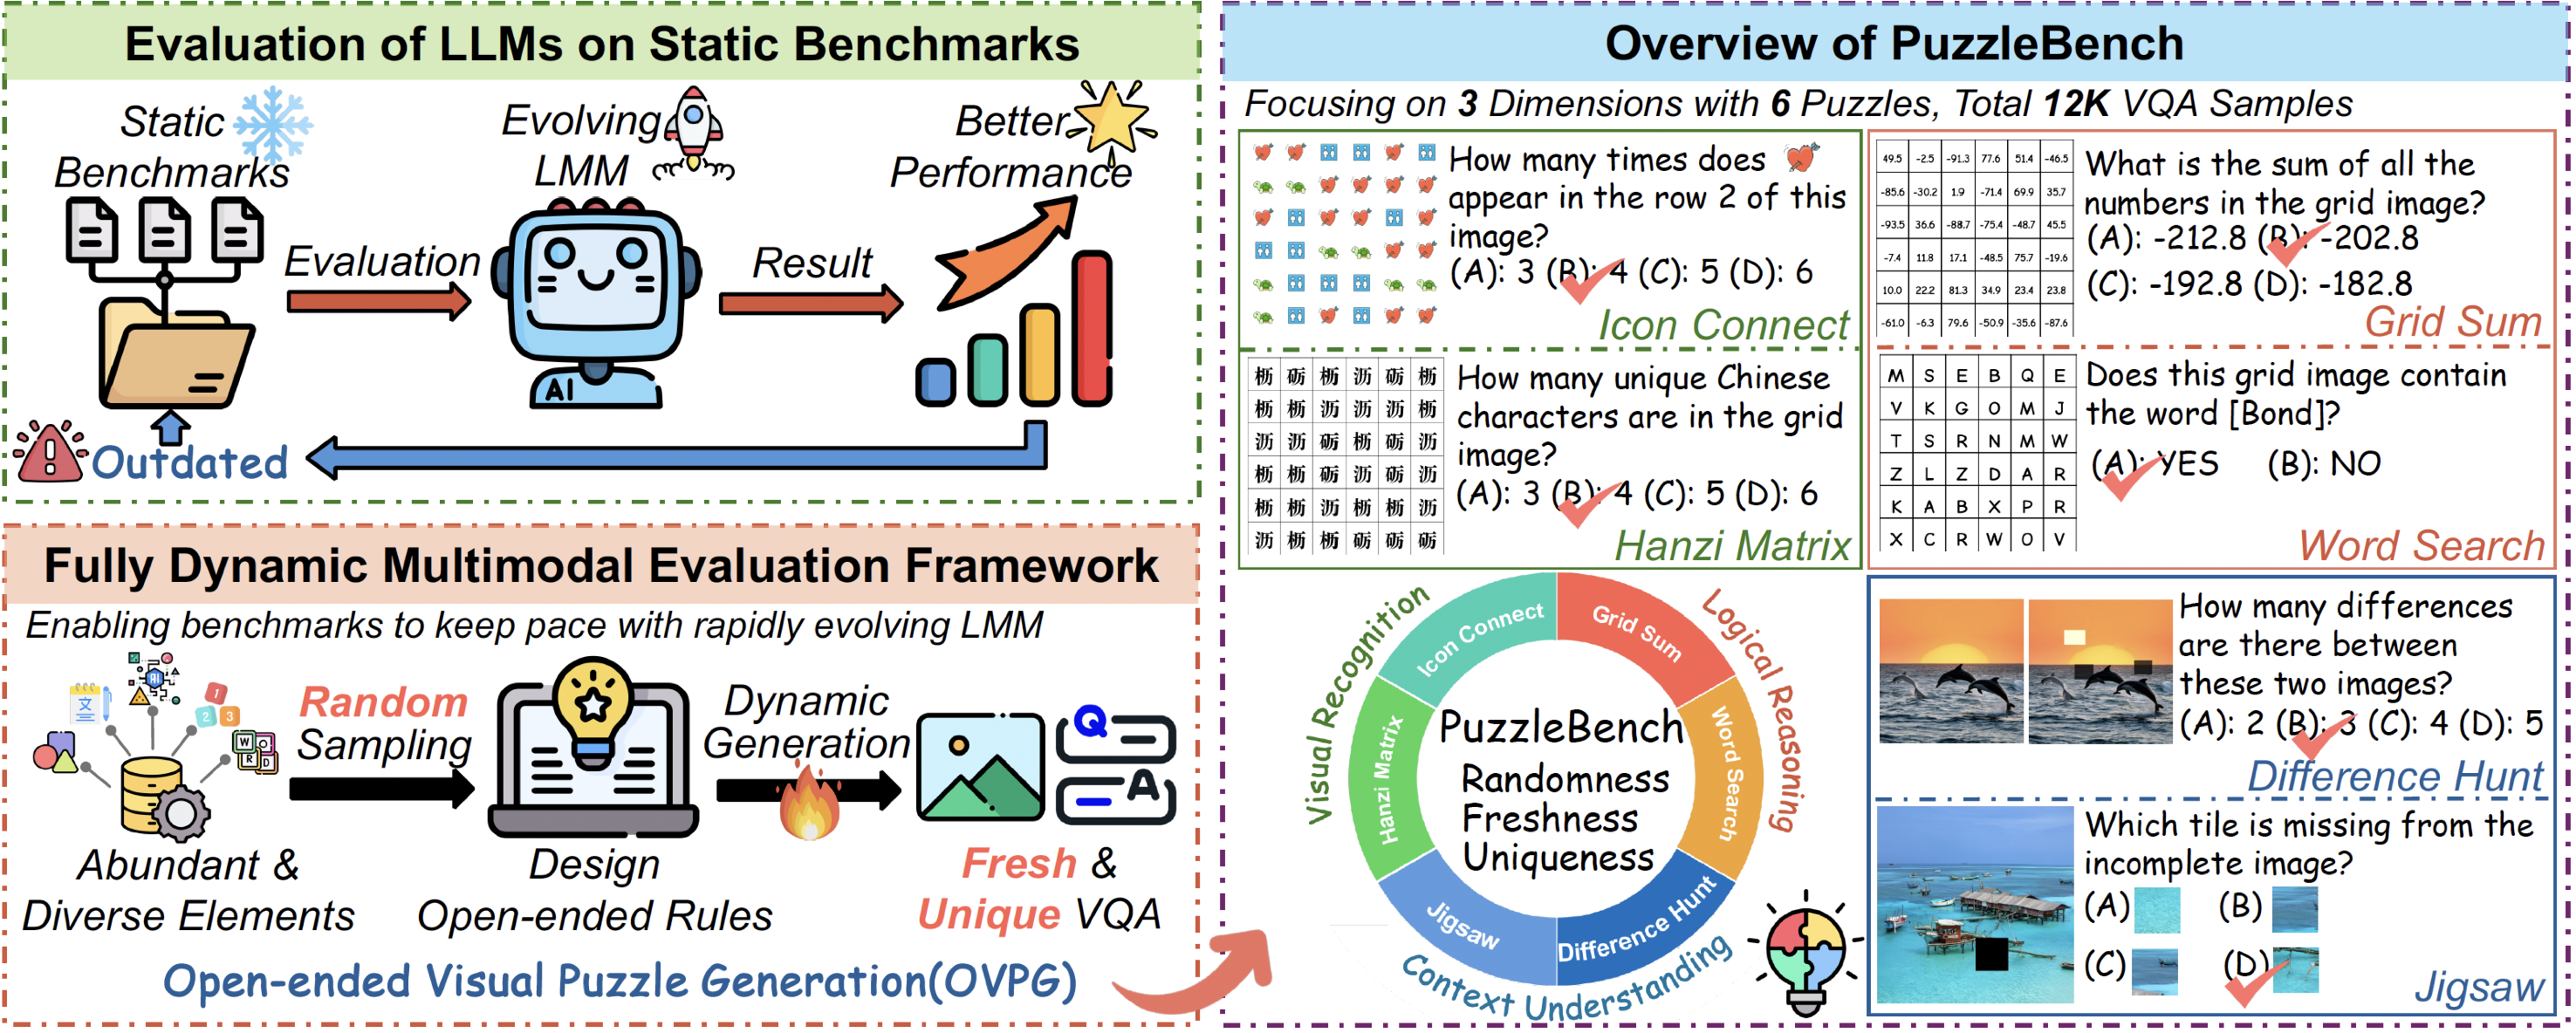 arXiv, 2025
In this paper, we construct PuzzleBench, a dynamic and scalable benchmark comprising 11,840 VQA samples, which features six carefully designed puzzle tasks targeting three core LMM competencies, visual recognition, logical reasoning, and context understanding.
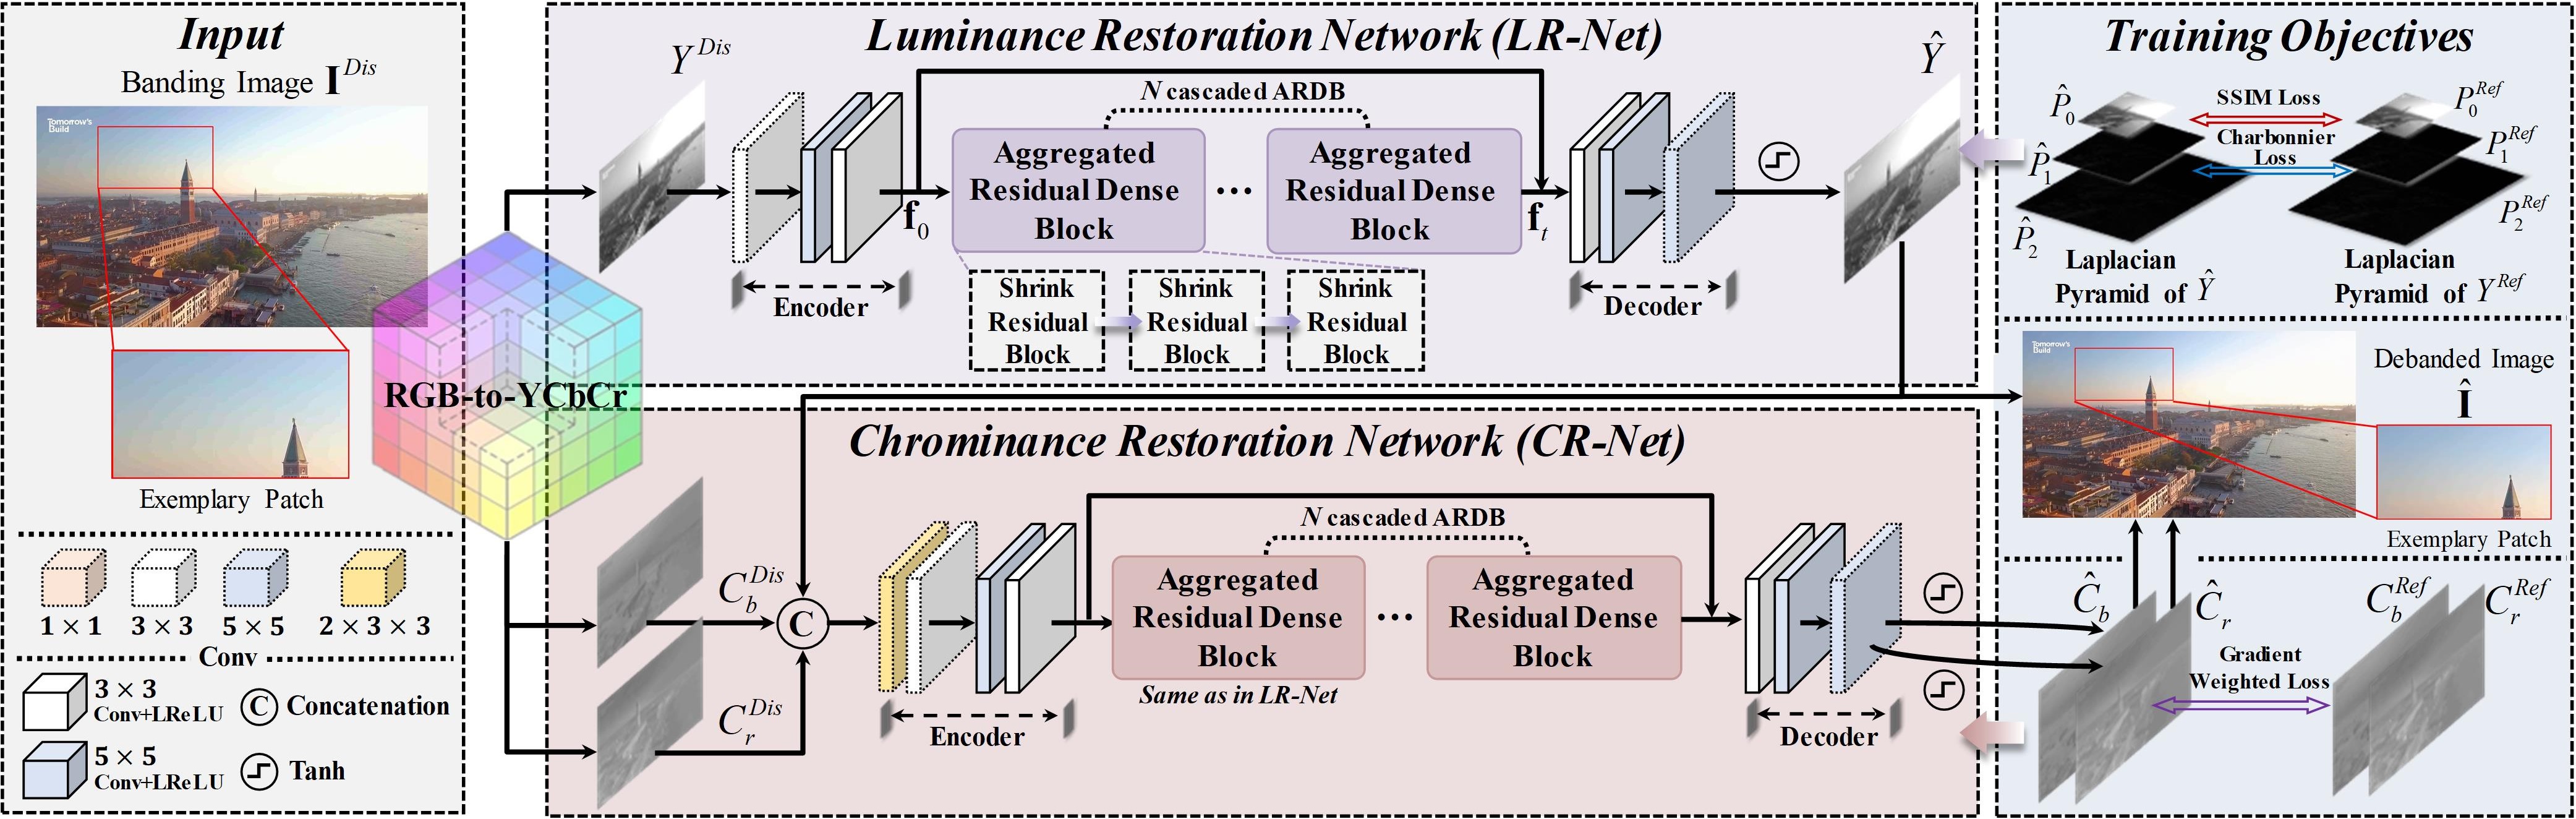 IEEE Transactions on Circuits and Systems for Video Technology, 2025
In this paper, we propose a unified deep neural network that explicitly disentangles the luminance and chrominance channels, and simultaneously recovers intensity gradients and color discontinuity from detection-free measurement in an end-to-end manner.
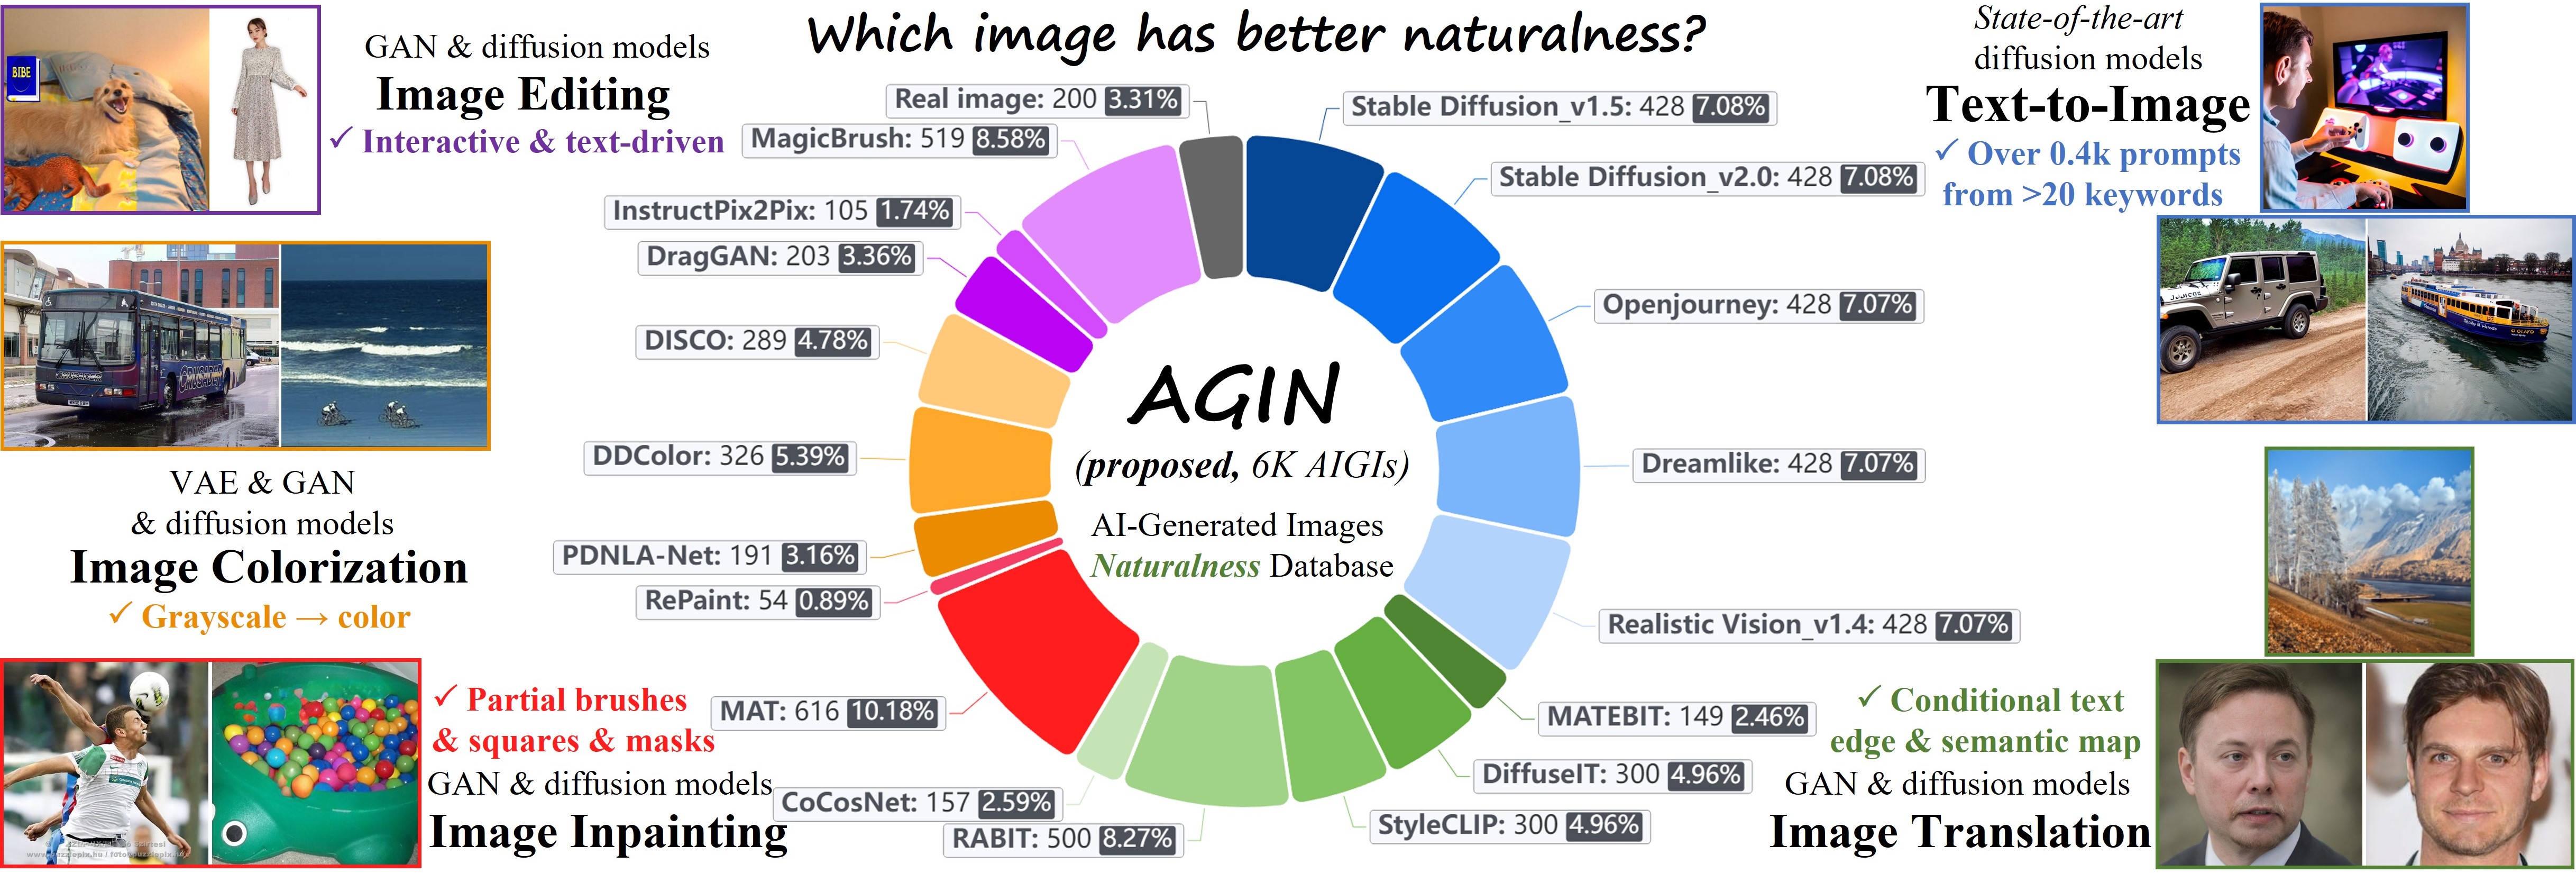 IEEE Transactions on Circuits and Systems for Video Technology, 2025
In this work, we construct the AI-Generated Image Naturalness (AGIN) dataset and propose the Joint Objective Image Naturalness evaluaTor (JOINT) to automatically assess the naturalness of AIGIs that align with human opinions.
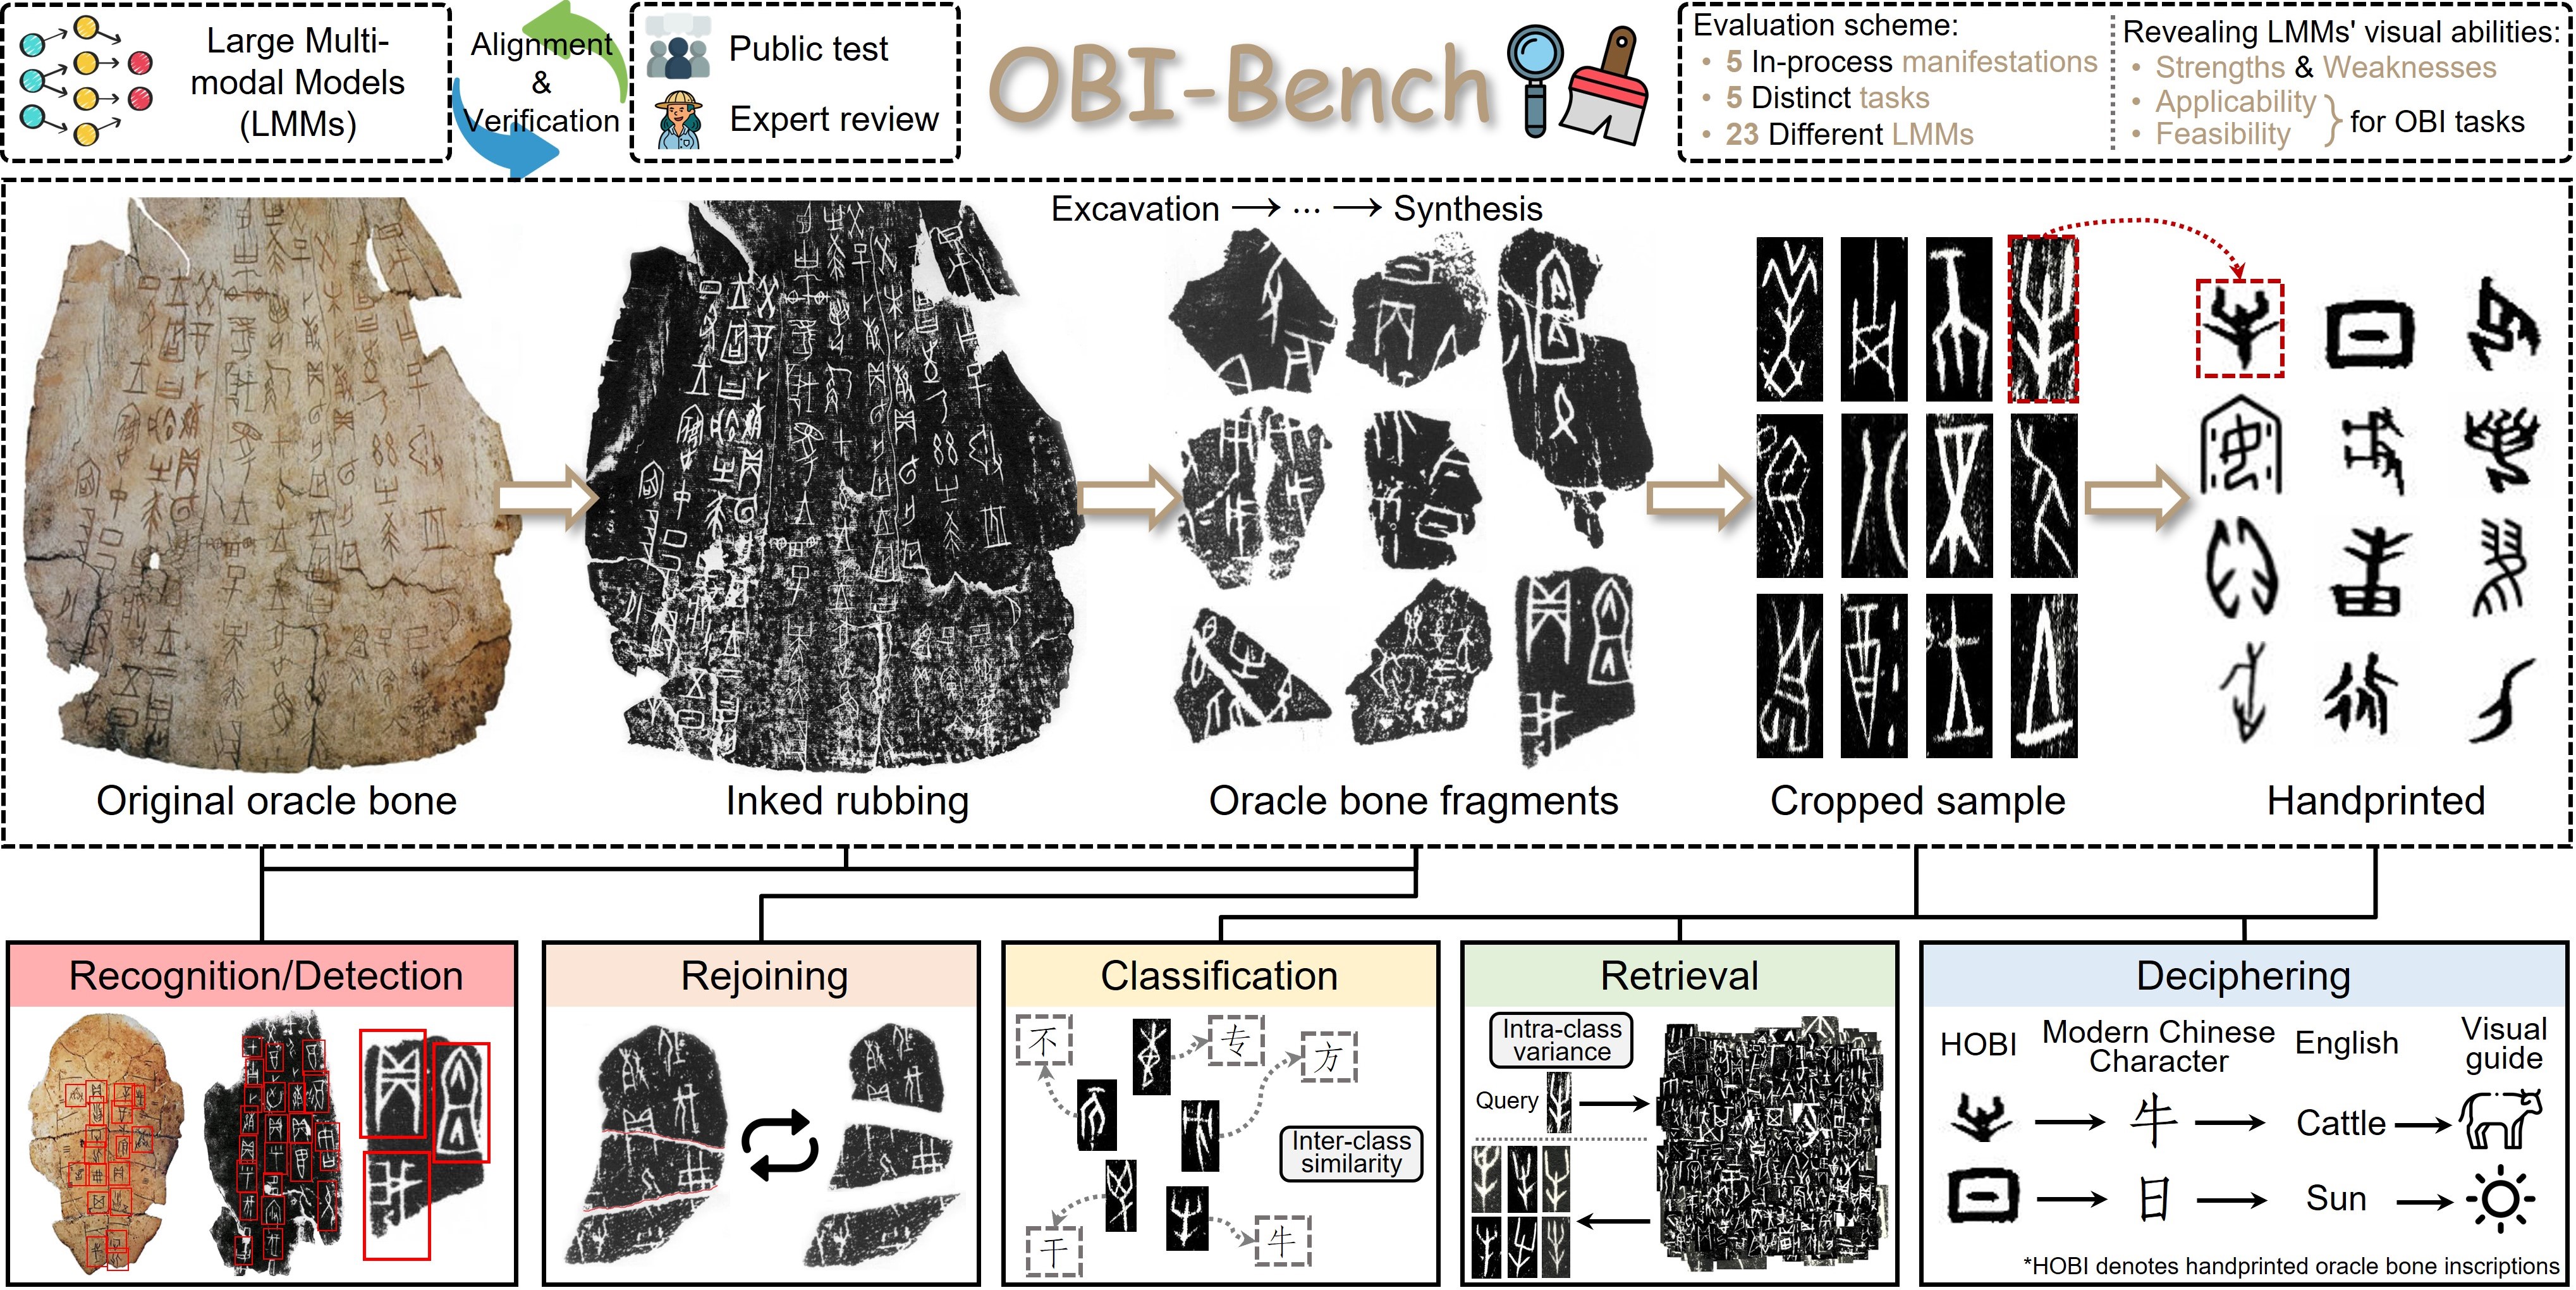 ICLR, 2025
In this work, we introduce OBI-Bench, a holistic benchmark crafted to systematically evaluate large multi-modal models (LMMs) on whole-process oracle bone inscriptions (OBI) processing tasks demanding expert-level domain knowledge and deliberate cognition.
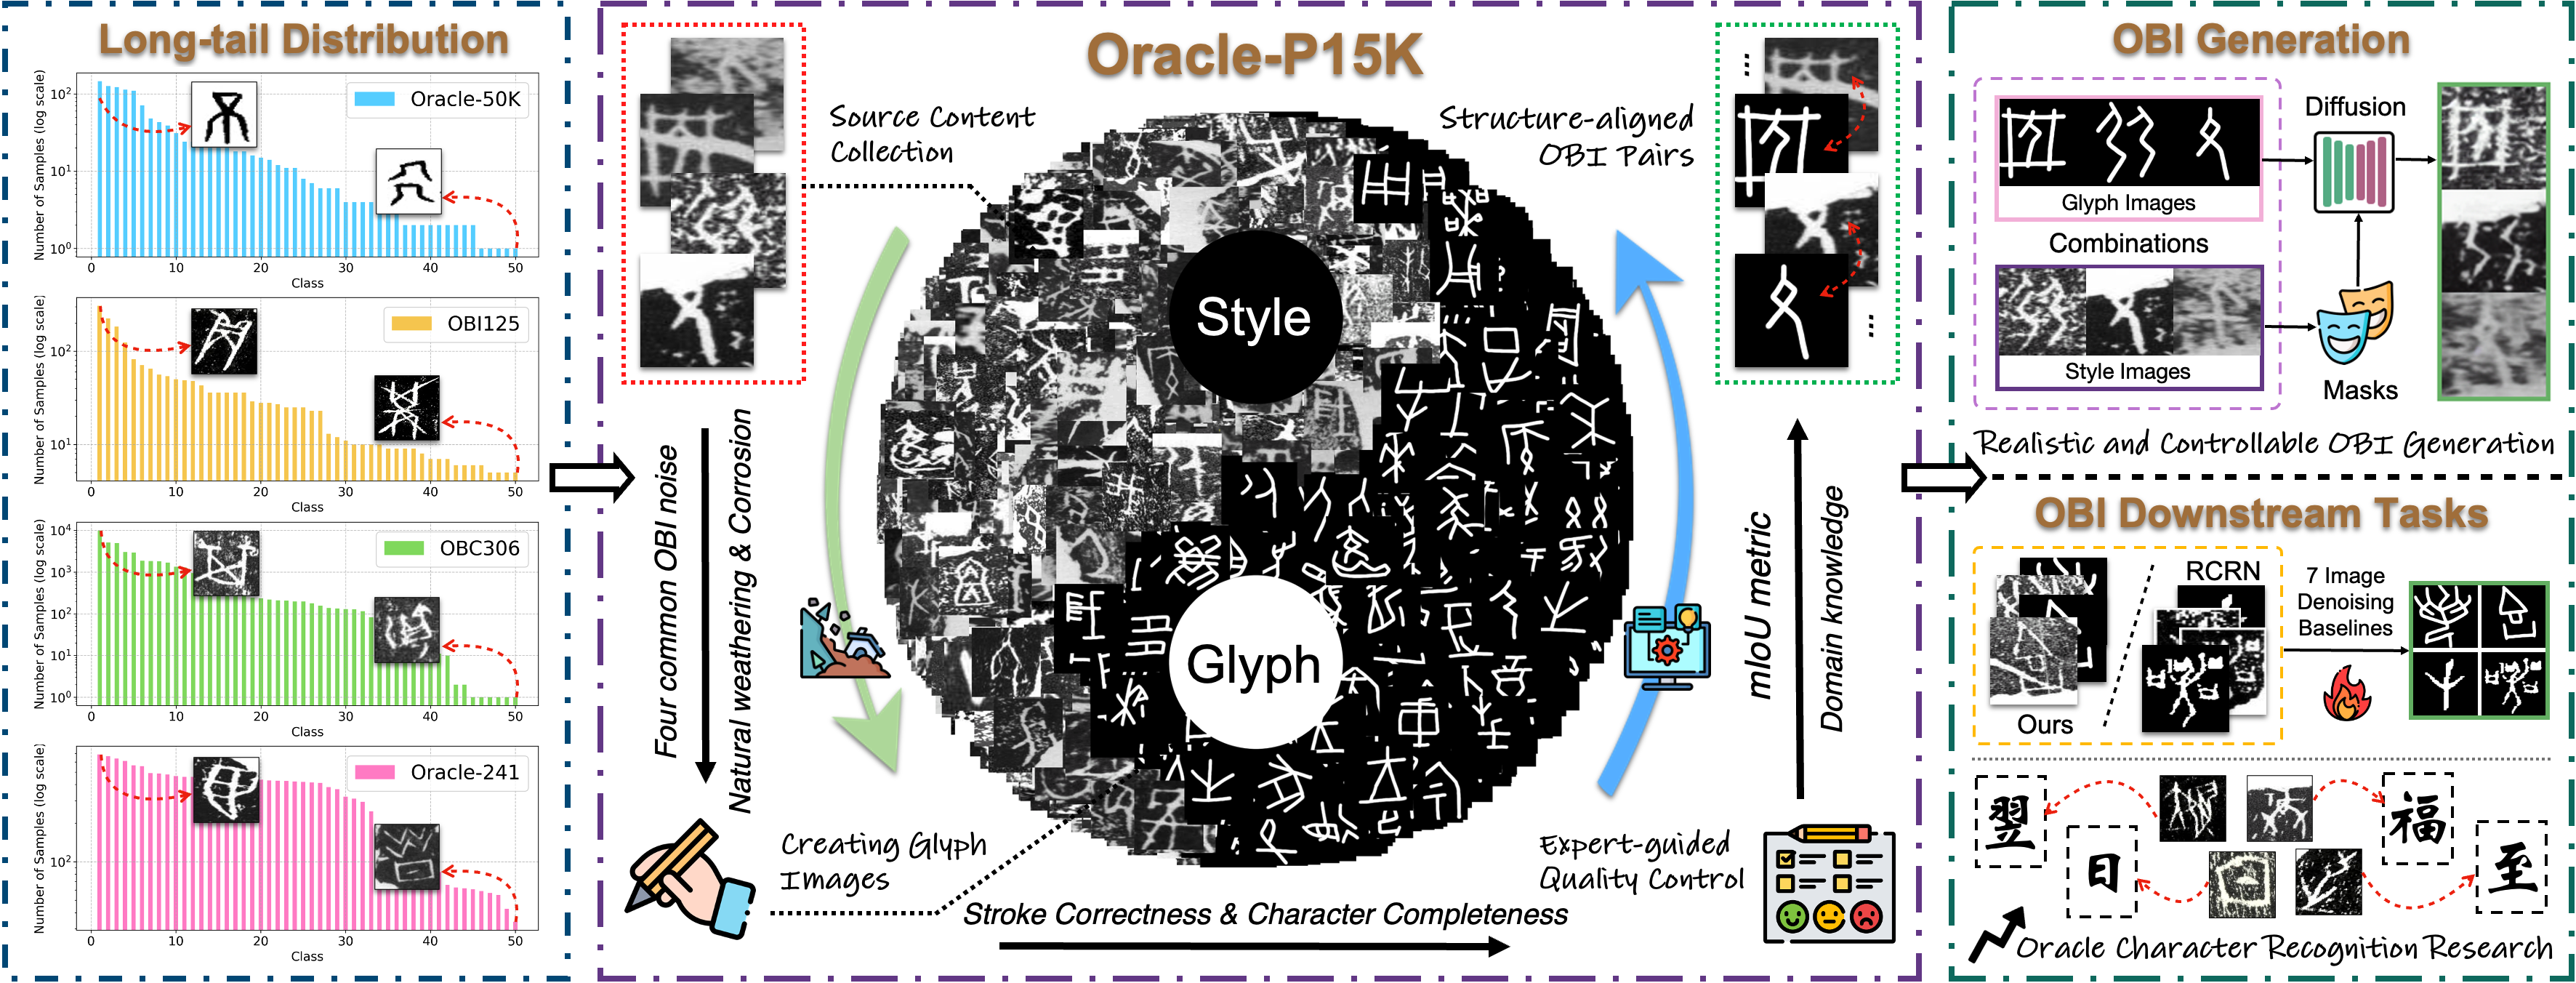 ACM MM, 2025 (Oral Recommendation)
In this paper, we present the Oracle-P15K, a structure-aligned OBI dataset for OBI generation and denoising, consisting of 14,542 images infused with domain knowledge from OBI experts. Based on this, we propose a diffusion model-based pseudo OBI generator, called OBIDiff, to achieve realistic and controllable OBI generation.
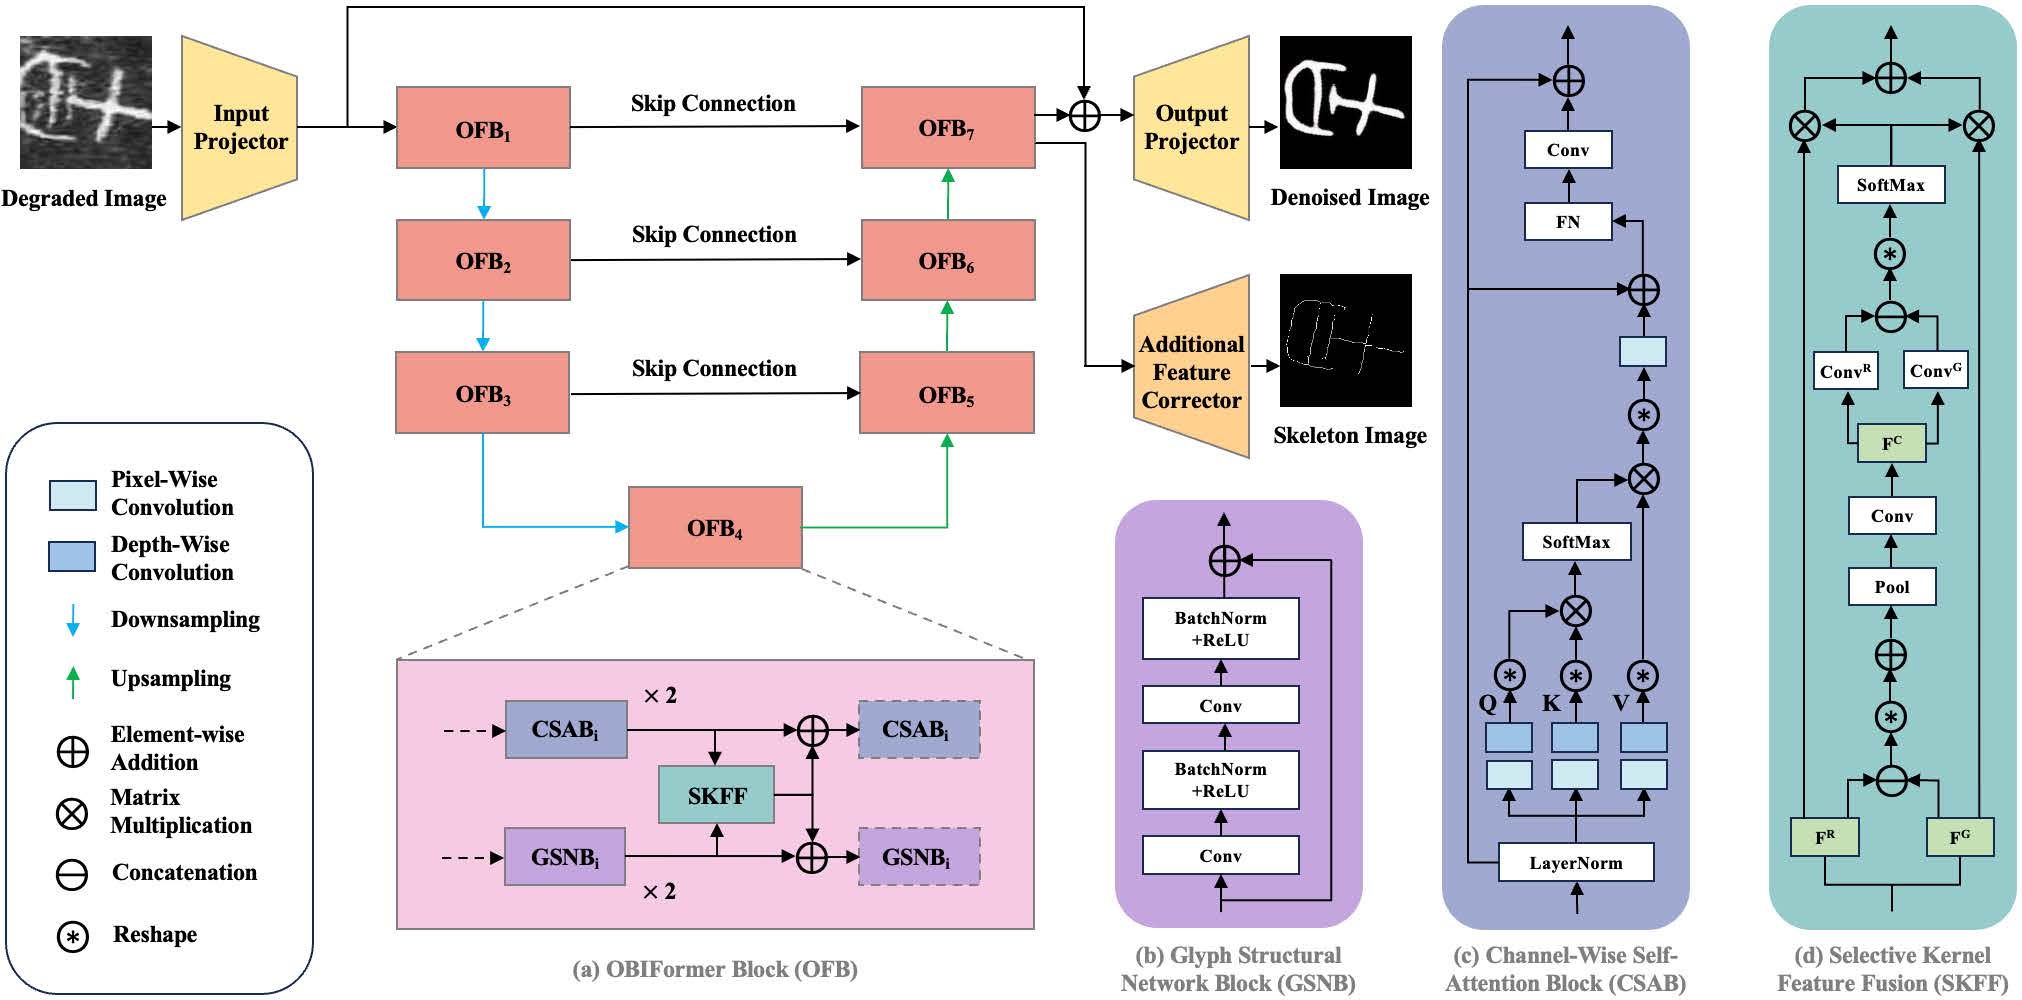 Displays, 2025
In this work, we propose OBIFormer, a fast attentive framework for high-precision Oracle bone inscriptions denoising.
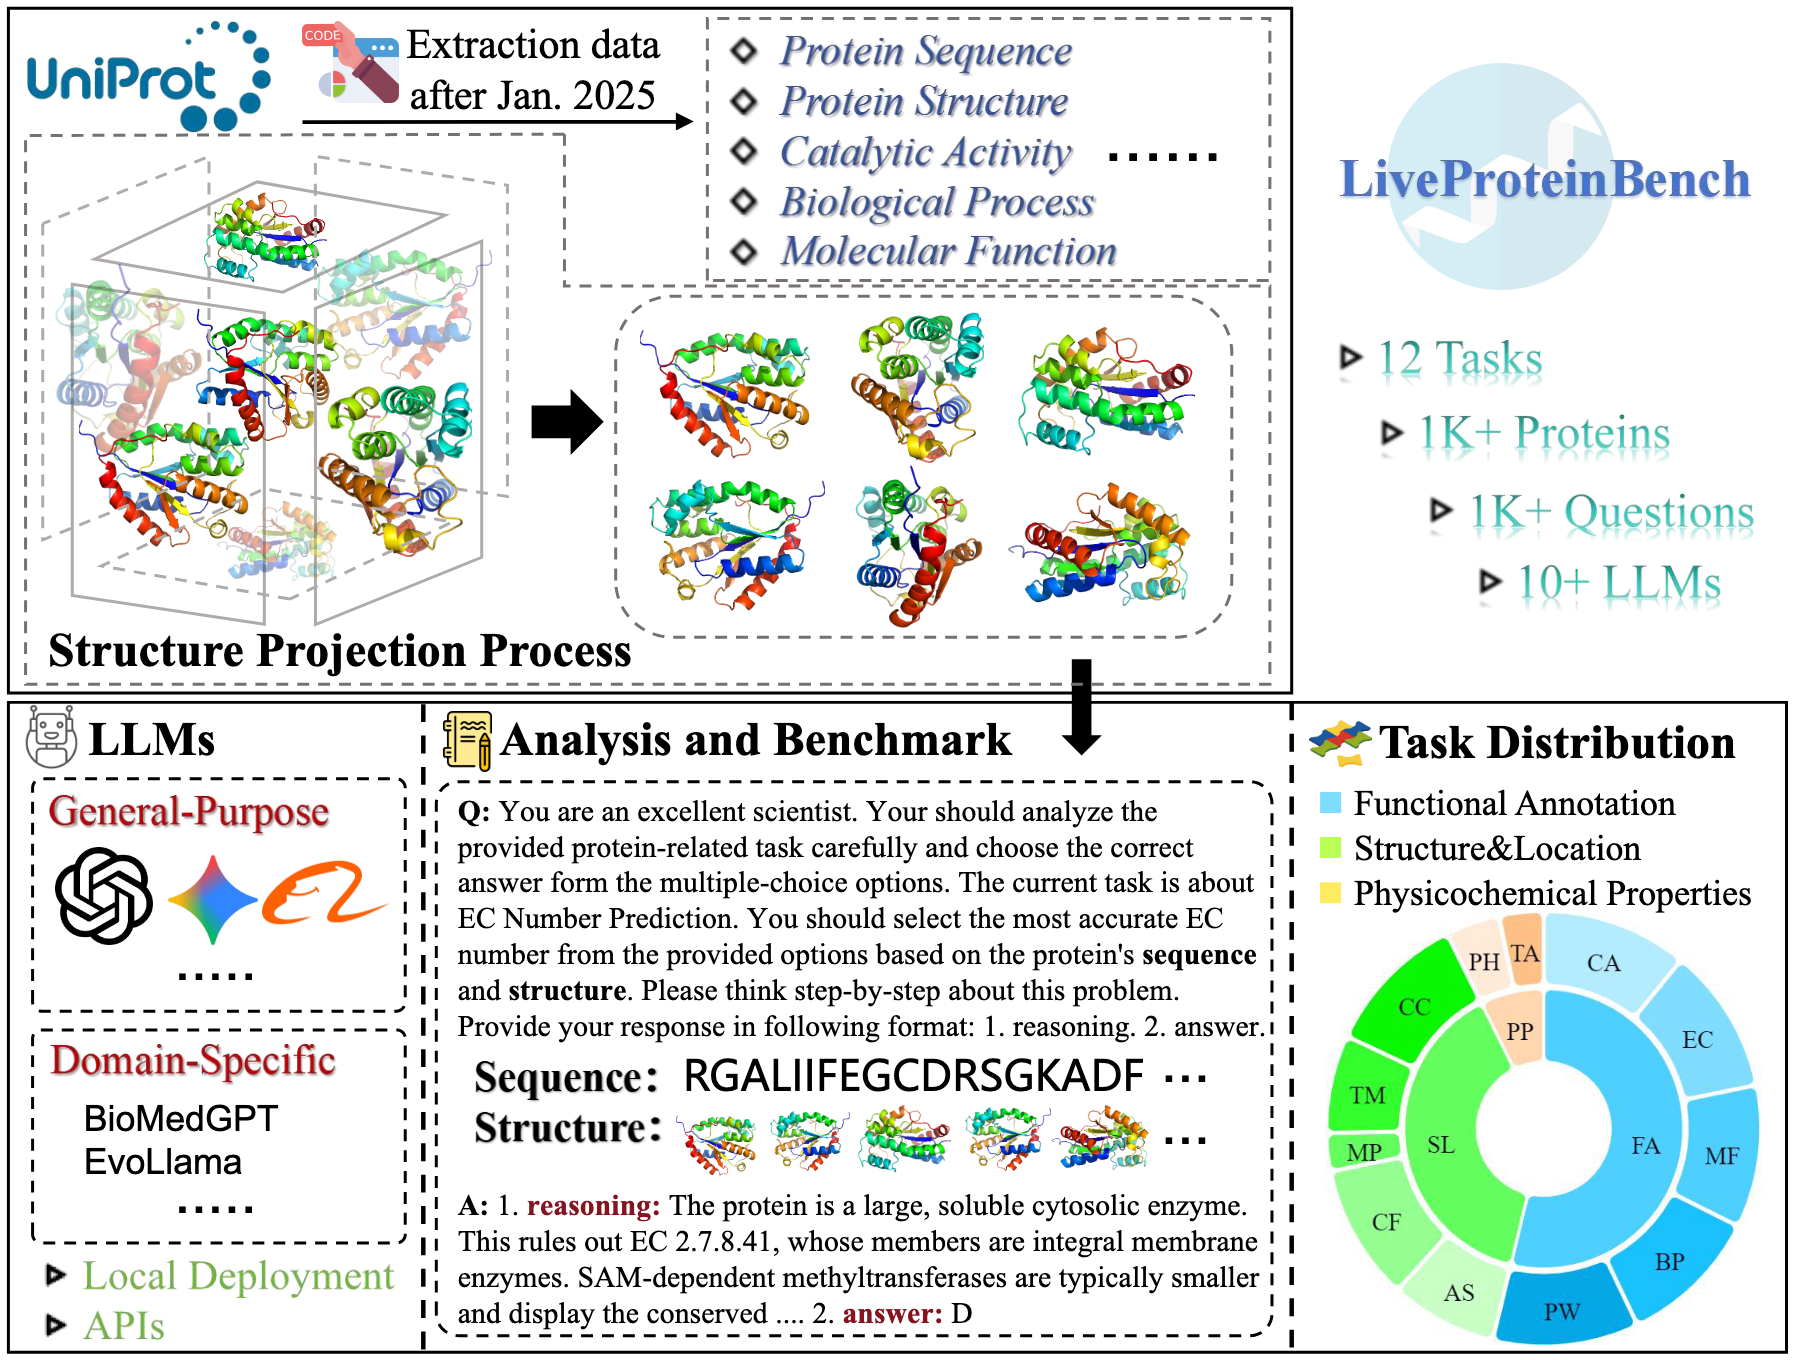 arXiv, 2025
In this paper, we introduce LiveProteinBench, a contamination-free, multimodal benchmark of 12 tasks for evaluating LLM performance on protein property and function prediction.
2024
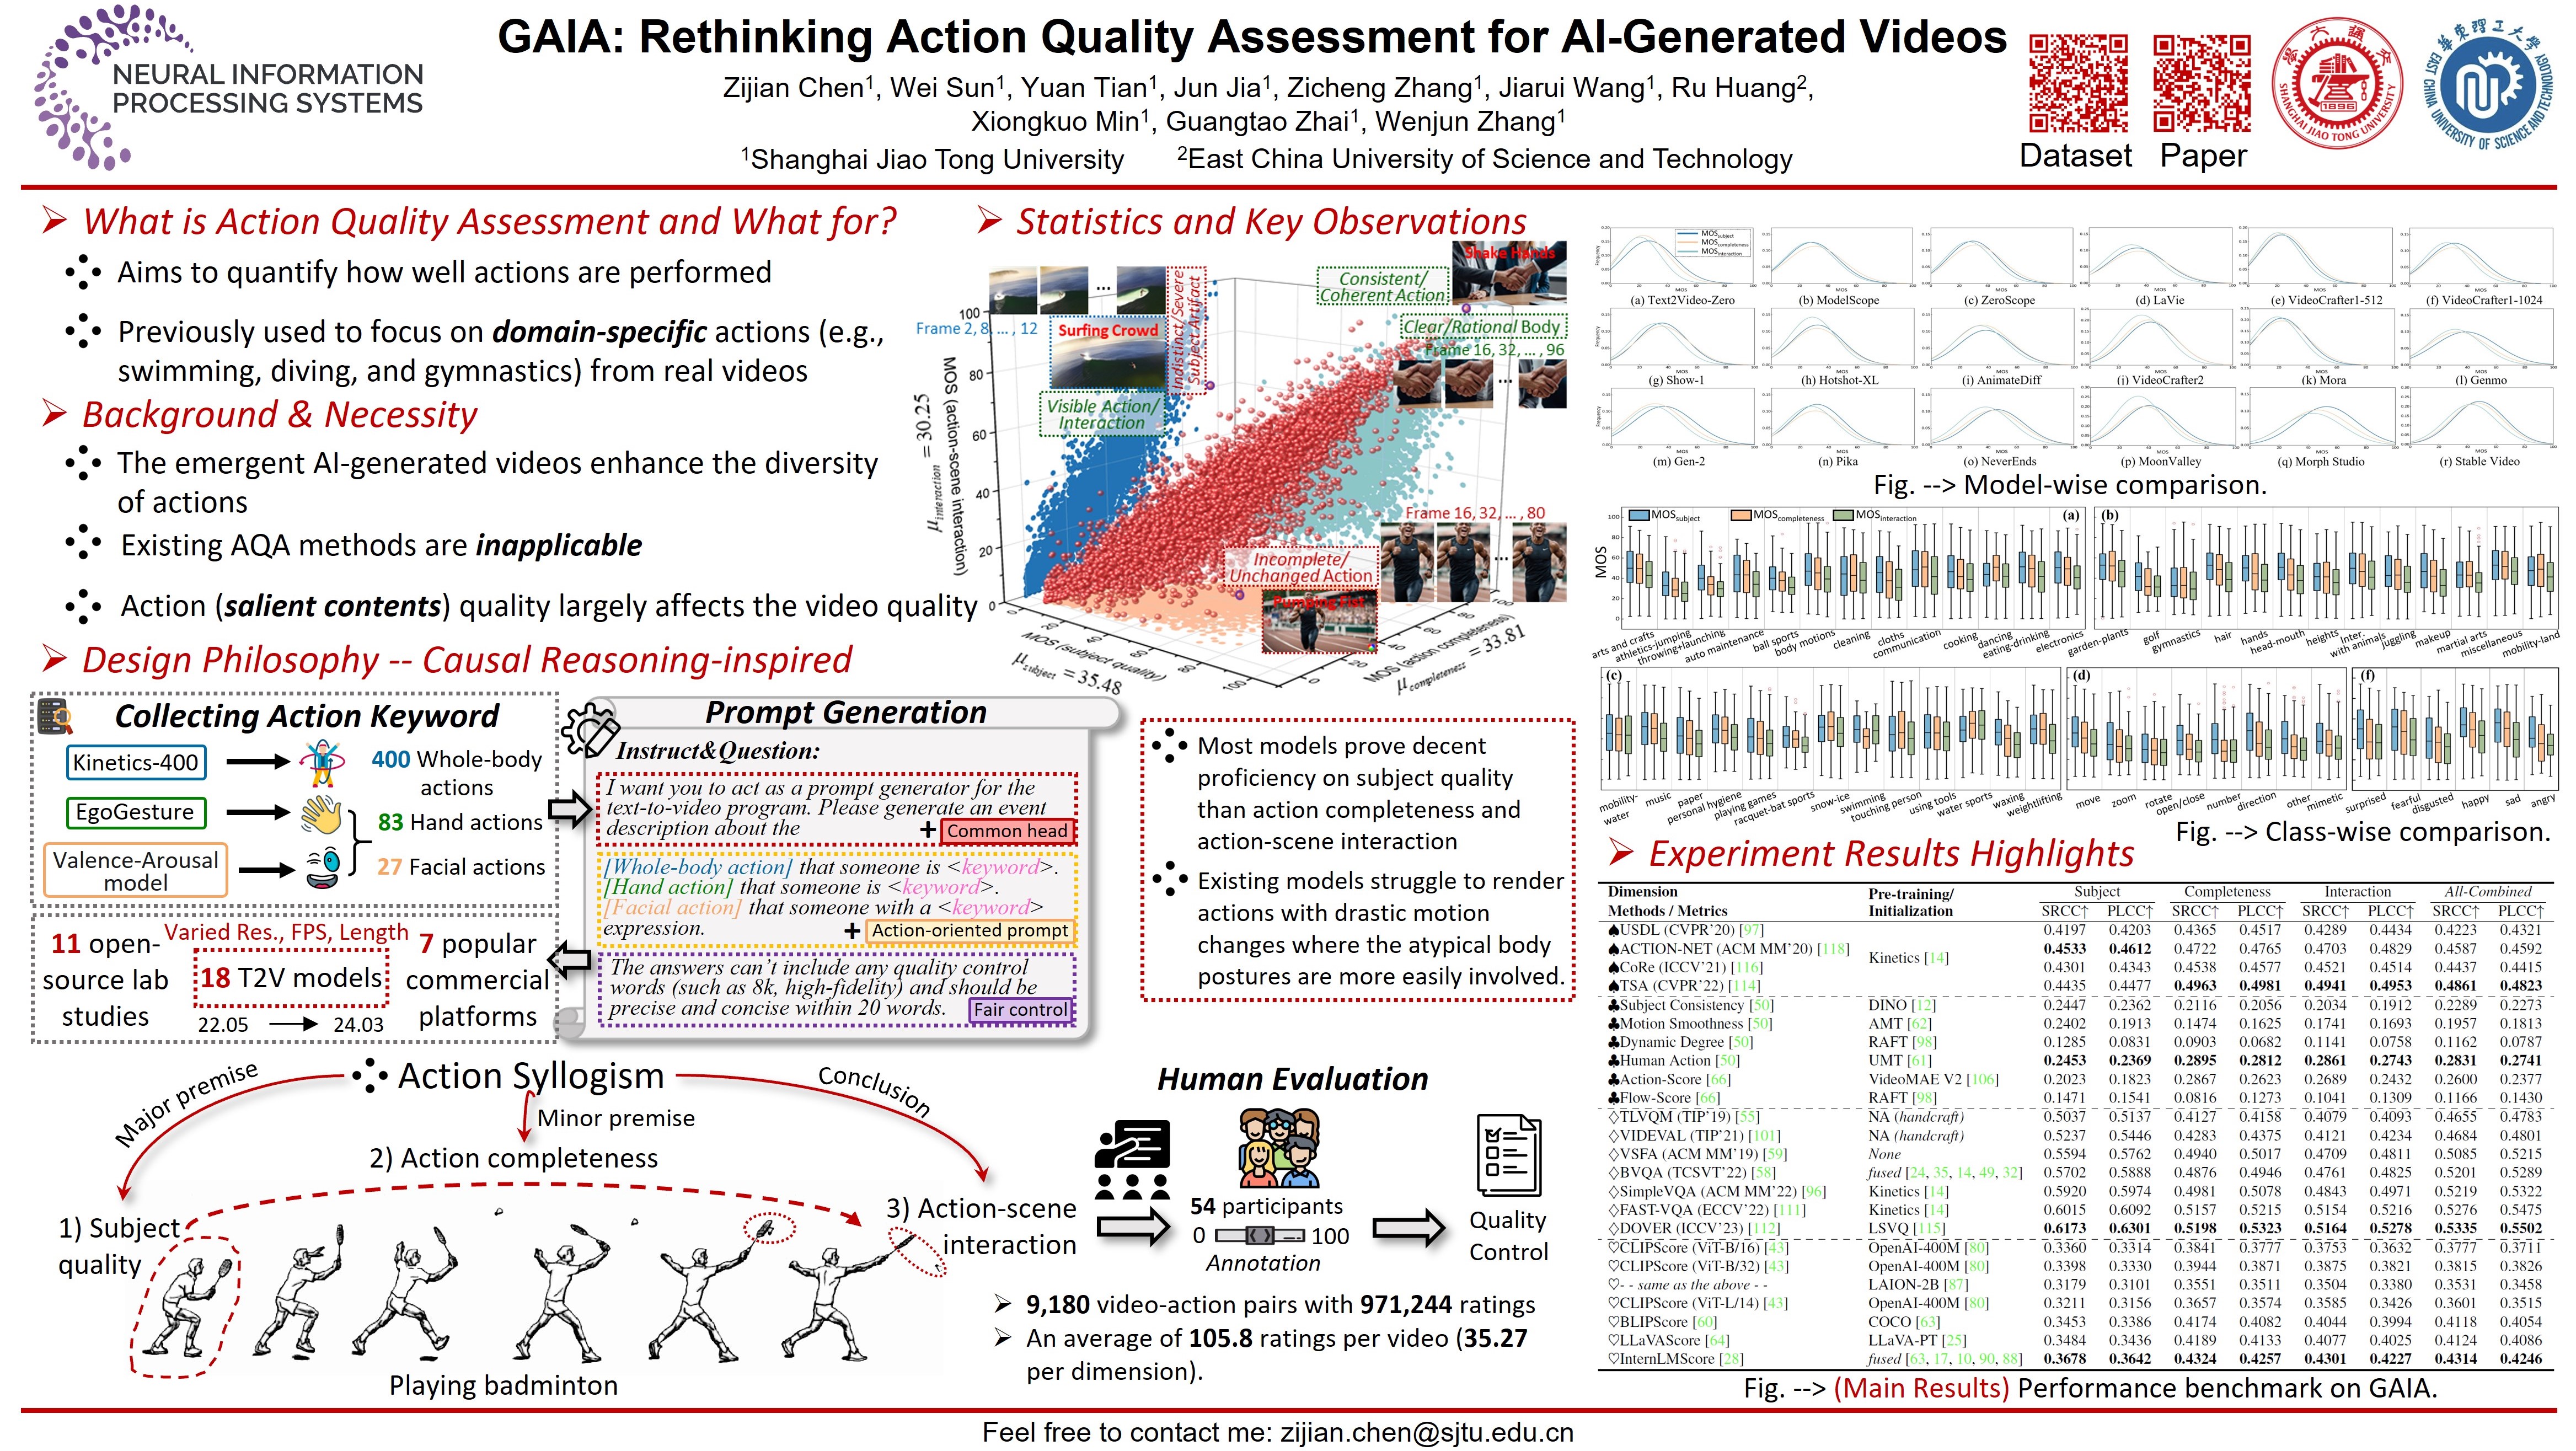 NeurIPS, 2024 (Spotlight Presentation)
In this work, we construct GAIA, a Generic AI-generated Action dataset, by conducting a large-scale subjective evaluation from a novel causal reasoning-based perspective, resulting in 971,244 ratings among 9,180 video-action pairs, and evaluate a suite of popular text-to-video models on their ability to generate visually rational actions.
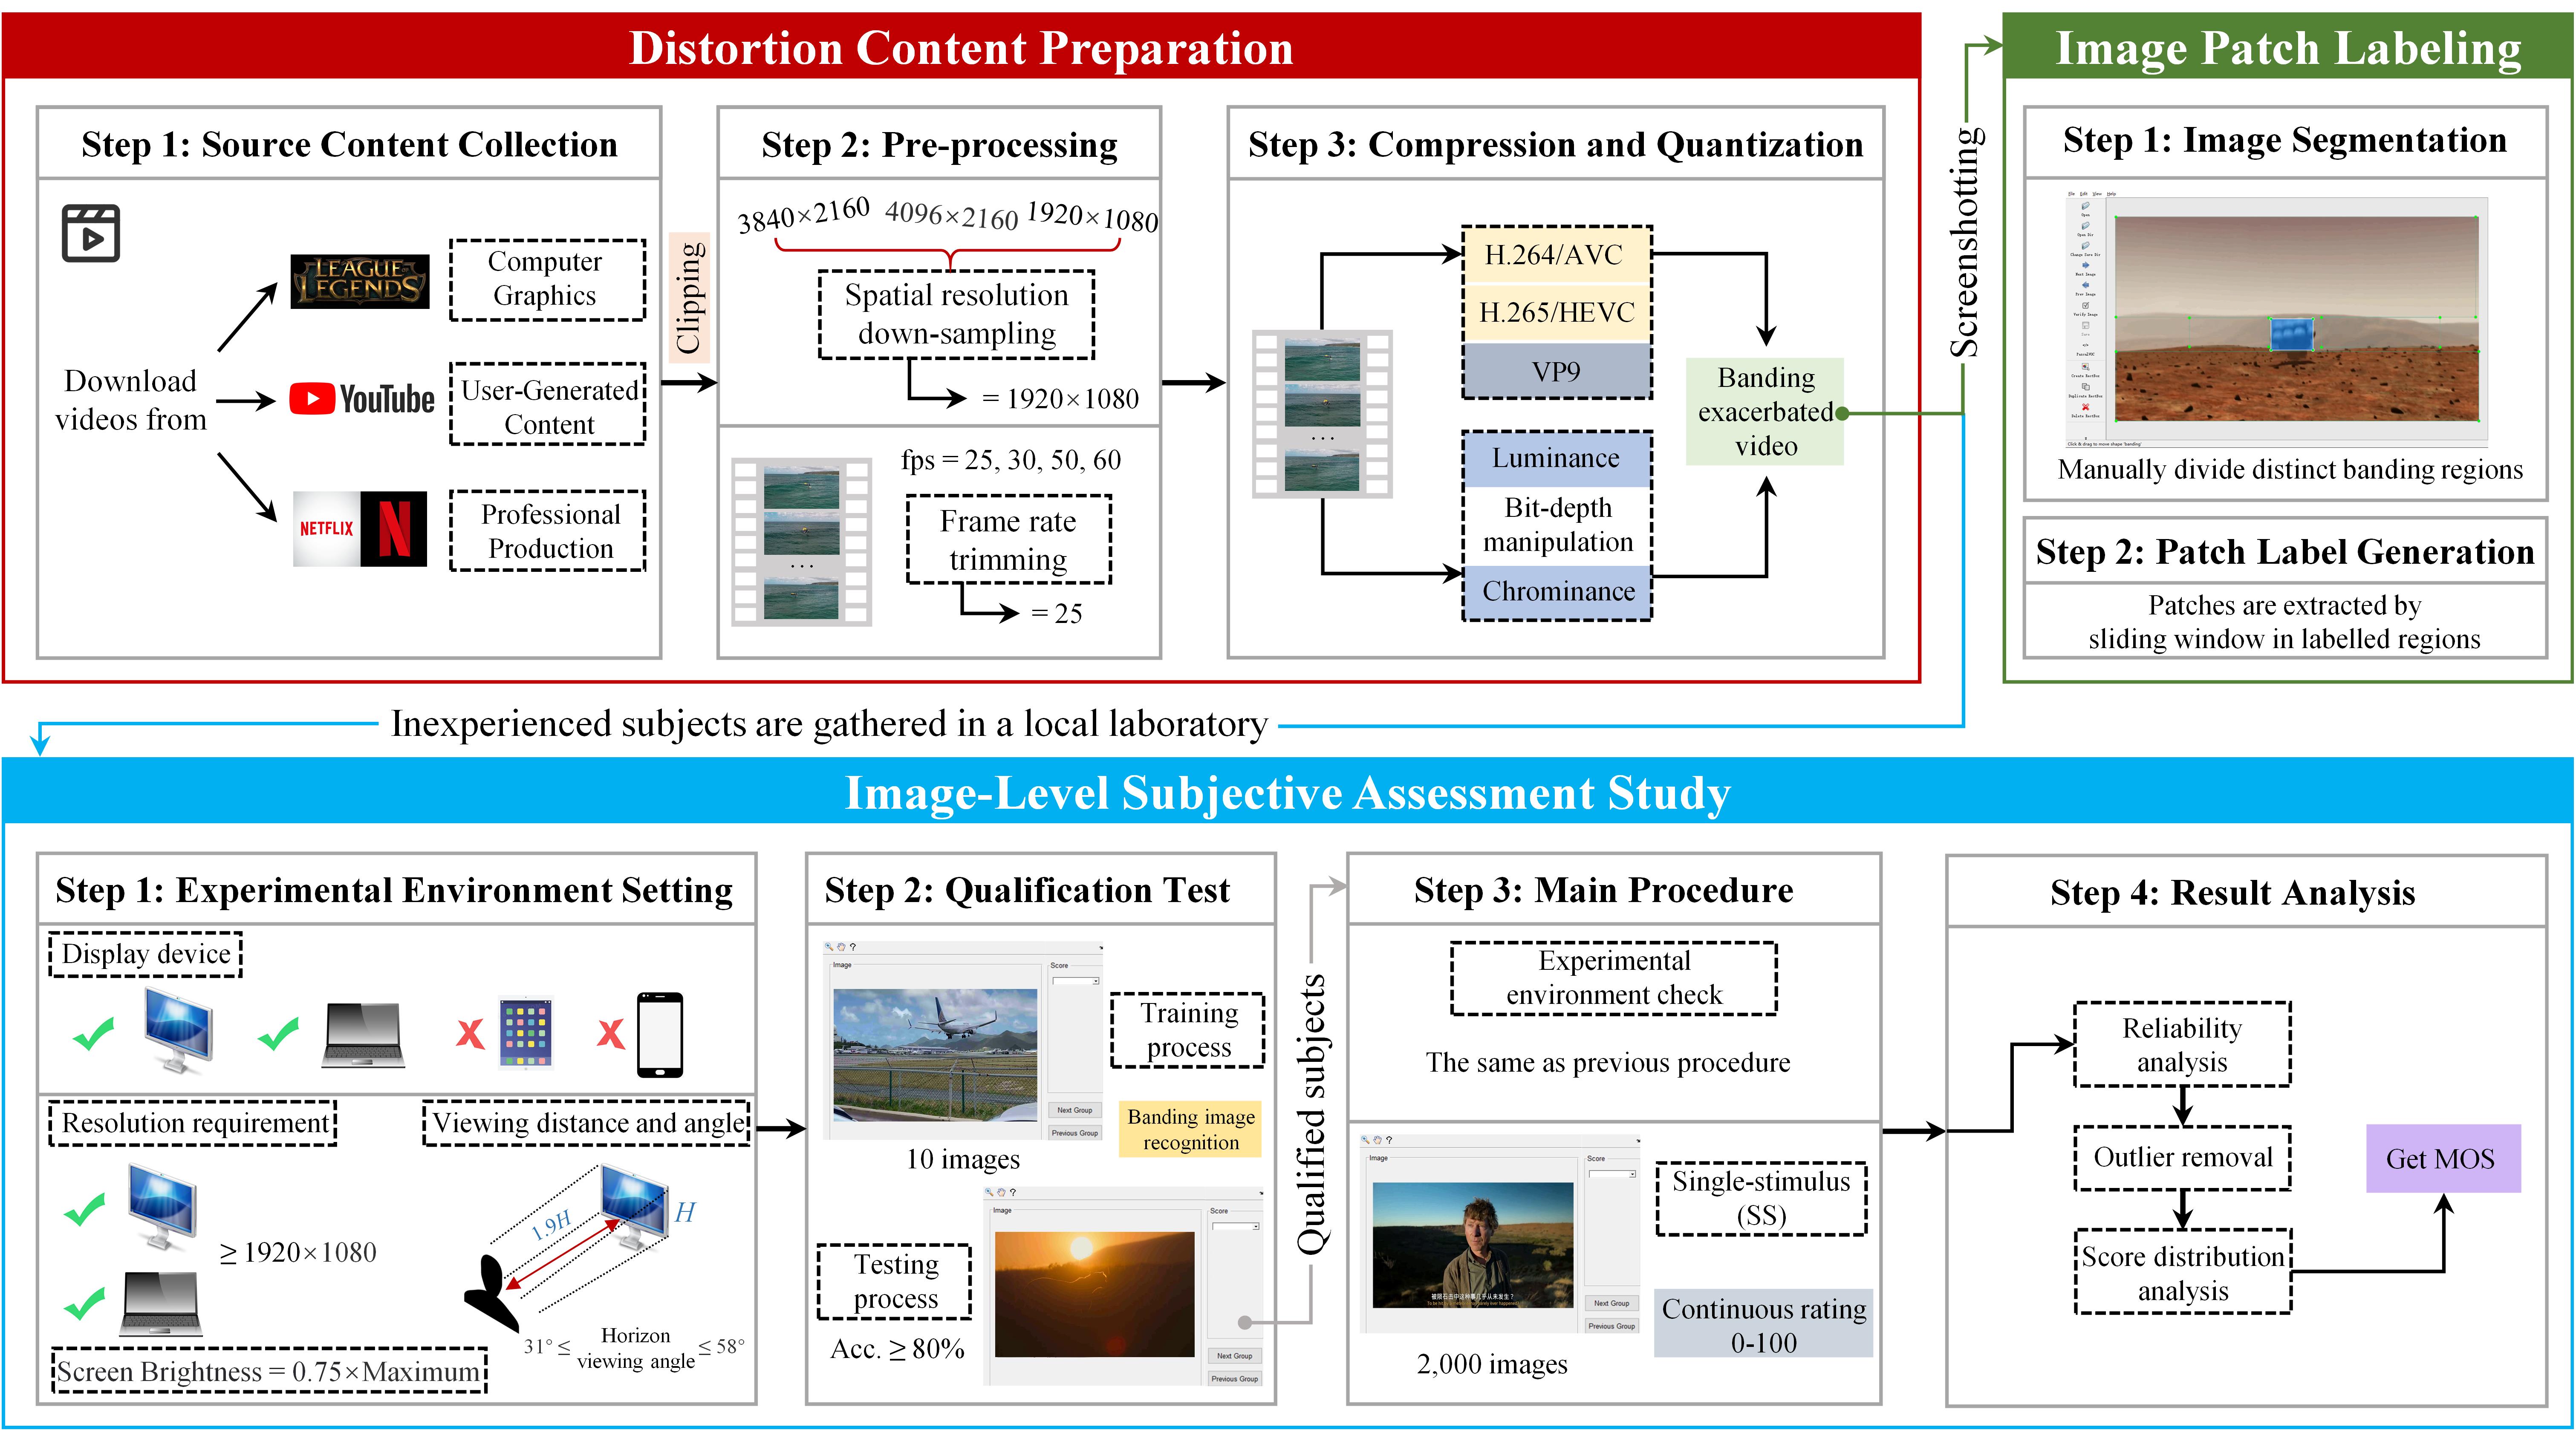 IEEE Transactions on Circuits and Systems for Video Technology, 2024
In this work, we build the Banding Artifact Noticeable Database (BAND-2k), which consists of 2,000 banding images generated by 15 compression and quantization schemes.
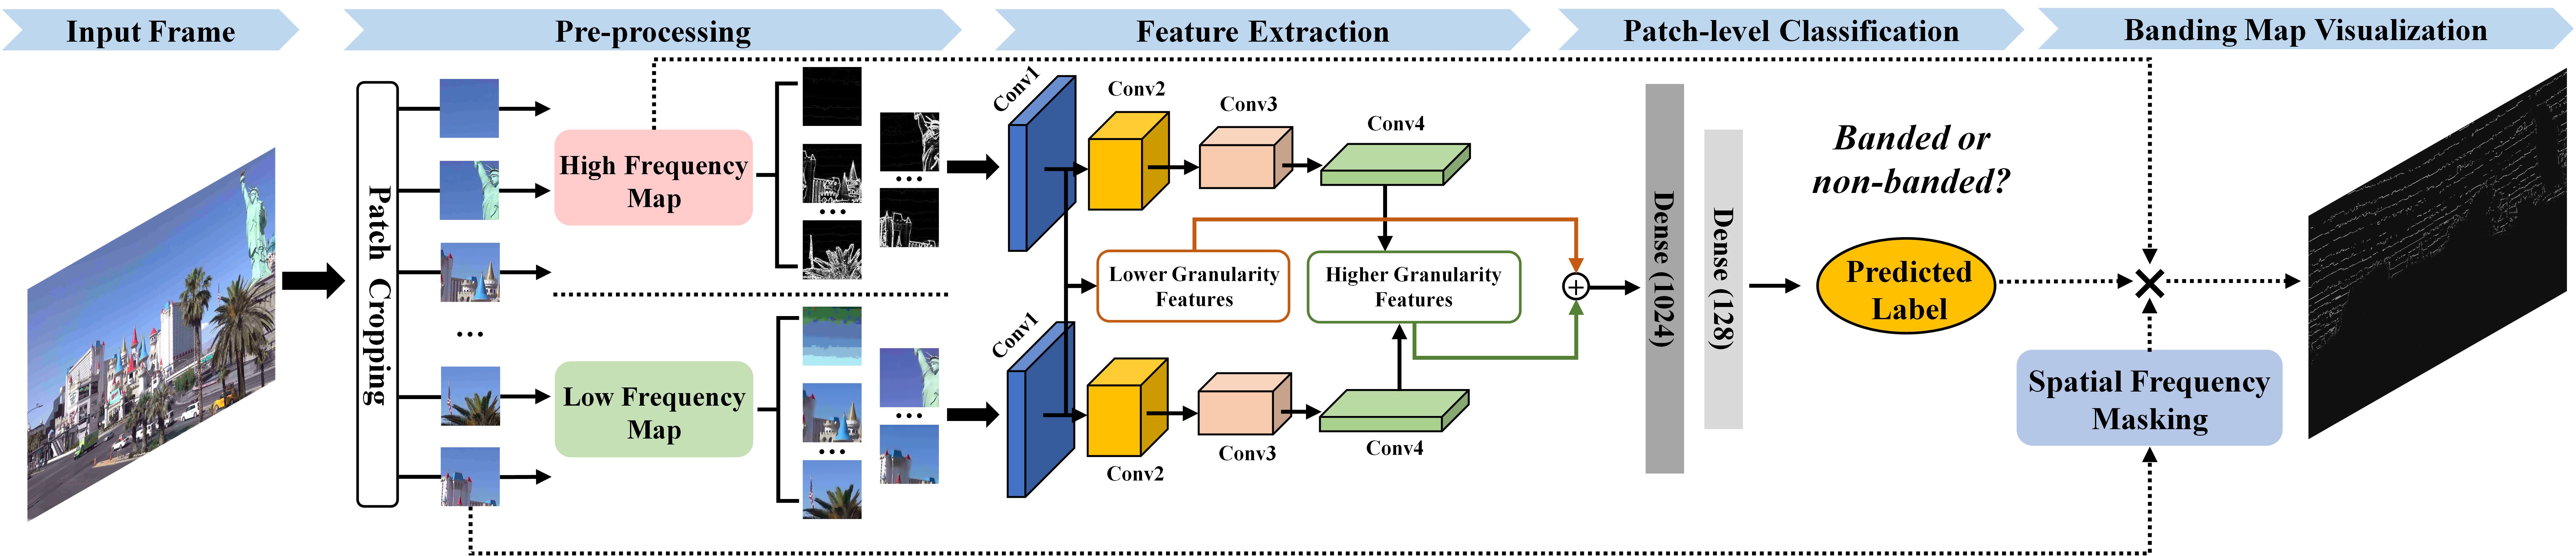 IEEE International Symposium on Circuits and Systems (ISCAS), 2024
In this paper, we develop a no-reference banding evaluator for banding detection and quality assessment by leveraging its frequency characteristics.